Human Computer Interaction

The Interface After Touchscreens: Could People Control Computers Through Intent Rather Than Input?

The next revolution in computing may not introduce a better way to interact with machines. It may make interaction itself almost invisible.

For decades, the evolution of computing has followed a remarkably consistent principle: humans must translate what they want into something a machine can recognize.

We learned to speak in commands. We learned to navigate keyboards, move cursors, click buttons, swipe screens, and tap icons. Every technological generation has made this translation faster, more intuitive, and increasingly accessible. Yet the underlying relationship has barely changed.

A person forms an intention. The person converts that intention into an input. The machine interprets the input. An interface presents the result.

Even the touchscreen, once considered a revolutionary departure from traditional computing, preserves this fundamental arrangement. We have removed the physical distance between the user and the interface, but we have not removed the interface as a requirement.

Now consider a different possibility.

You are reading a document on your computer. You reach a complicated paragraph and want to understand its implications. Instead of highlighting the text, opening another application, and typing a question, the system recognizes that you are trying to understand something more deeply. It offers a contextual explanation without interrupting your reading.

You are reviewing a moderation queue. You encounter content that requires a nuanced policy judgment. Instead of navigating several dashboards, you mentally establish the context you need, and the environment reorganizes around the task.

You are designing a product. You imagine a different arrangement of elements, and the system presents a possible interpretation of that intention.

No command. No gesture. No navigation.

Just intention translated into an appropriate computational response.

This is the possibility of Intent-Native Computing: a paradigm in which computers are designed to respond not only to what people explicitly do, but to what they are demonstrably trying to accomplish.

1. From Human-Computer Interaction to Human-Computer Understanding

Traditional interfaces are built around observable actions.

Clicking communicates selection. Typing communicates language. Swiping communicates navigation. Voice communicates a spoken instruction.

These interactions are relatively easy for machines to recognize because they are explicit and measurable.

Intent, however, is fundamentally different.

A person can look at a photograph without wanting to open it. They can pause over a sentence because they are confused, distracted, or simply thinking. They can move a cursor toward a button without having decided to click it.

The distinction between an action and an intention is where the next interface revolution could begin.

Instead of treating every interaction as an isolated event, an intent-native system would interpret a combination of contextual signals: the user’s current task, interaction history, explicit preferences, application state, and voluntarily provided inputs.

More advanced systems could incorporate physiological or neural signals, where appropriate and with informed consent. But the central breakthrough would not necessarily be reading thoughts. It would be developing a much better understanding of the relationship between human goals and machine actions.

This distinction matters.

A computer that responds to every detectable signal is simply a more invasive computer. A computer that understands when it should act, when it should wait, and when it should ask is something fundamentally different.

The objective is not to make machines more perceptive at any cost. It is to make them more contextually intelligent without making human autonomy negotiable.

2. The Interface May Become an Environment Rather Than a Destination

Today’s software assumes that users must enter an interface to accomplish something.

We open applications, locate features, navigate menus, configure settings, and move between different environments to complete a single objective.

But what if the interface stopped being a destination?

Imagine an operating system that does not organize itself primarily around applications, windows, or menus. Instead, it organizes itself around the user’s current intention.

When someone is researching, the environment prioritizes relevant information, comparisons, and source credibility. When someone is creating, it surfaces creative tools and supporting material. When someone is evaluating a decision, it presents competing possibilities, uncertainties, and consequences.

The interface becomes dynamic.

It does not disappear completely. Rather, it becomes an adaptive layer that continuously negotiates between what the user is trying to achieve and what the system can responsibly facilitate.

We could call this the ambient interface.

Unlike conventional interfaces, which require people to understand the software’s structure, an ambient interface would allow software to adapt its structure to the user’s evolving objectives.

The implications are significant.

Software products may eventually compete less on the number of features they offer and more on how intelligently they recognize the moment in which those features become useful.

The best interface might not be the one with the fewest buttons.

It might be the one that understands when a button should exist at all.

3. The Most Difficult Problem: Knowing What Not to Do

There is a dangerous assumption hidden inside the idea of intent-based computing: that human intention is always clear.

It isn’t.

People frequently change their minds. They explore possibilities without committing to them. They experience contradictory emotions. They think about actions they have no intention of performing.

A system that interprets curiosity as consent, hesitation as rejection, or emotional response as authorization could create a completely new category of technological failure.

Consider a simple example.

A user is reading an article about financial risk. The system detects repeated attention toward investment-related information. Should it automatically open an investment platform?

Absolutely not.

Attention is not intention. Intention is not authorization. Authorization is not permission for unlimited action.

These distinctions should become foundational principles of future interface design.

An intent-native system needs what might be called an Intent Verification Layer.

This layer would distinguish between three states:

  • Exploration: The user is considering, observing, learning, or evaluating something.
  • Intention: The user has demonstrated a sufficiently clear objective.
  • Authorization: The user has explicitly permitted the system to perform a consequential action.

The system could respond differently at each stage. It might surface information during exploration, prepare a suggested action when intention becomes clear, and require confirmation before executing sensitive or irreversible operations.

This introduces a radical design principle: the most intelligent interface is not necessarily the one that anticipates everything. It is the one that understands the limits of its authority.

4. What Happens to Content Moderation When Interfaces Understand Intent?

One of the most interesting implications of intent-native computing lies beyond traditional product design.

It could fundamentally change how content platforms approach safety and moderation.

Current moderation systems primarily evaluate observable content and behavior. They analyze text, images, videos, account activity, distribution patterns, and contextual signals to determine whether something violates a platform’s policies.

But context is often difficult to establish.

The same phrase can represent satire, harassment, education, reporting, criticism, or genuine advocacy. A photograph can be documentary evidence or exploitative material. A conversation can be adversarial without being abusive.

Intent-aware systems could introduce another contextual dimension into moderation workflows.

For example, imagine a moderator reviewing a potentially harmful post. Rather than simply receiving a binary classification, the moderation environment could surface the surrounding conversational context, relevant policy provisions, previous decisions, uncertainty indicators, and alternative interpretations.

The system would not claim to know the author’s private thoughts. Instead, it would help the moderator understand the observable communicative purpose of the content.

This could move moderation from isolated content classification toward more context-sensitive decision support.

However, there is an important boundary.

Platforms must never treat inferred psychological states or presumed private intentions as definitive evidence of a policy violation. Doing so could introduce serious risks involving discrimination, false positives, surveillance, and the suppression of legitimate expression.

The future of moderation should not be built around machines claiming to know what people think.

It should be built around machines becoming better at explaining what they can establish, what they cannot establish, and where human judgment remains essential.

5. The New Digital Divide: Who Controls the Interpretation of Intent?

Every major technological shift creates a new question of power.

The keyboard era gave power to those who could communicate with computers. The touchscreen era made computing more accessible through direct manipulation. The AI era is increasingly giving machines the ability to interpret and generate information.

Intent-native computing introduces a more sensitive question:

Who gets to decide what a person means?

If an operating system interprets intentions, it inevitably gains influence over how people interact with information, make decisions, and exercise control.

A commercial platform could prioritize actions based on inferred preferences. An employer could be tempted to measure employee attention. An educational platform could confuse curiosity with engagement. An advertising system could attempt to turn momentary interest into commercial opportunity.

The consequences could be much more invasive than conventional behavioral tracking.

For this reason, the next generation of interfaces must be designed around a principle that deserves the same importance as security and usability: interpretive sovereignty.

Interpretive sovereignty means that individuals retain meaningful control over how their intentions are interpreted by digital systems.

It requires:

  • Local processing of sensitive signals wherever technically feasible.
  • Clear consent before collecting physiological or neural data.
  • The ability to inspect, correct, and disable inferred preferences.
  • Strict separation between intention detection and commercial targeting.
  • No automatic execution of consequential actions based solely on inferred intent.
  • Interfaces that communicate uncertainty instead of presenting guesses as facts.

The objective should be to create computers that understand people without giving institutions unrestricted power to interpret them.

6. The Post-Touchscreen Era May Not Be Screenless

It is tempting to imagine that intent-based computing will eliminate keyboards, touchscreens, microphones, and conventional devices.

That may never happen, and perhaps it shouldn’t.

Physical inputs provide something that invisible interactions cannot always guarantee: clarity.

A button press can communicate an explicit decision. A keyboard can provide precision. A touchscreen can offer direct manipulation. Voice can make interaction accessible in situations where physical input is inconvenient.

These technologies are not necessarily obsolete. They may become complementary layers within a more intelligent interaction model.

The real transition is not from touch to thought.

It is from input-dependent computing to intention-aware computing.

The screen may remain. The keyboard may remain. But neither should dictate how every digital experience must be structured.

The future could involve a combination of explicit commands, contextual assistance, adaptive environments, and carefully governed neural or physiological interfaces.

The defining innovation would be the ability to move between these interaction modes without forcing users to translate every intention into a predefined sequence of actions.

Conclusion: The Next Interface Should Understand the Human, Not Just the Command

The history of computing has largely been a history of reducing the effort required to operate machines.

We moved from punch cards to keyboards, from keyboards to graphical interfaces, from graphical interfaces to touchscreens, and from touchscreens toward conversational AI.

Each transition reduced a different form of friction.

But perhaps we have been asking the wrong question all along.

Instead of asking how humans can become better at communicating with computers, we should ask how computers can become better at understanding human objectives without compromising human freedom.

Intent-native computing offers a possible answer.

It is not simply about controlling devices through brain signals, replacing gestures with thoughts, or building software that predicts our next move. It is about creating a different relationship between people and technology: one in which the machine can recognize context, understand uncertainty, adapt to evolving goals, and know when it does not have permission to act.

That final capability may become the most important one.

Because a computer that can anticipate what we want is powerful.

A computer that can distinguish what we want from what we merely consider is more sophisticated.

But a computer that knows when not to act, even when it believes it understands us, may represent the real breakthrough.

The future of computing may not be defined by the disappearance of the interface. It may be defined by the disappearance of our obligation to think like a computer just to use one.
satellite

Satellites That Never Retire: The Rise of Robotic Repair, Refueling, and Upgrades in Orbit

What if the next revolution in space technology isn’t launching better satellites, but building a way to keep the ones we already have alive?

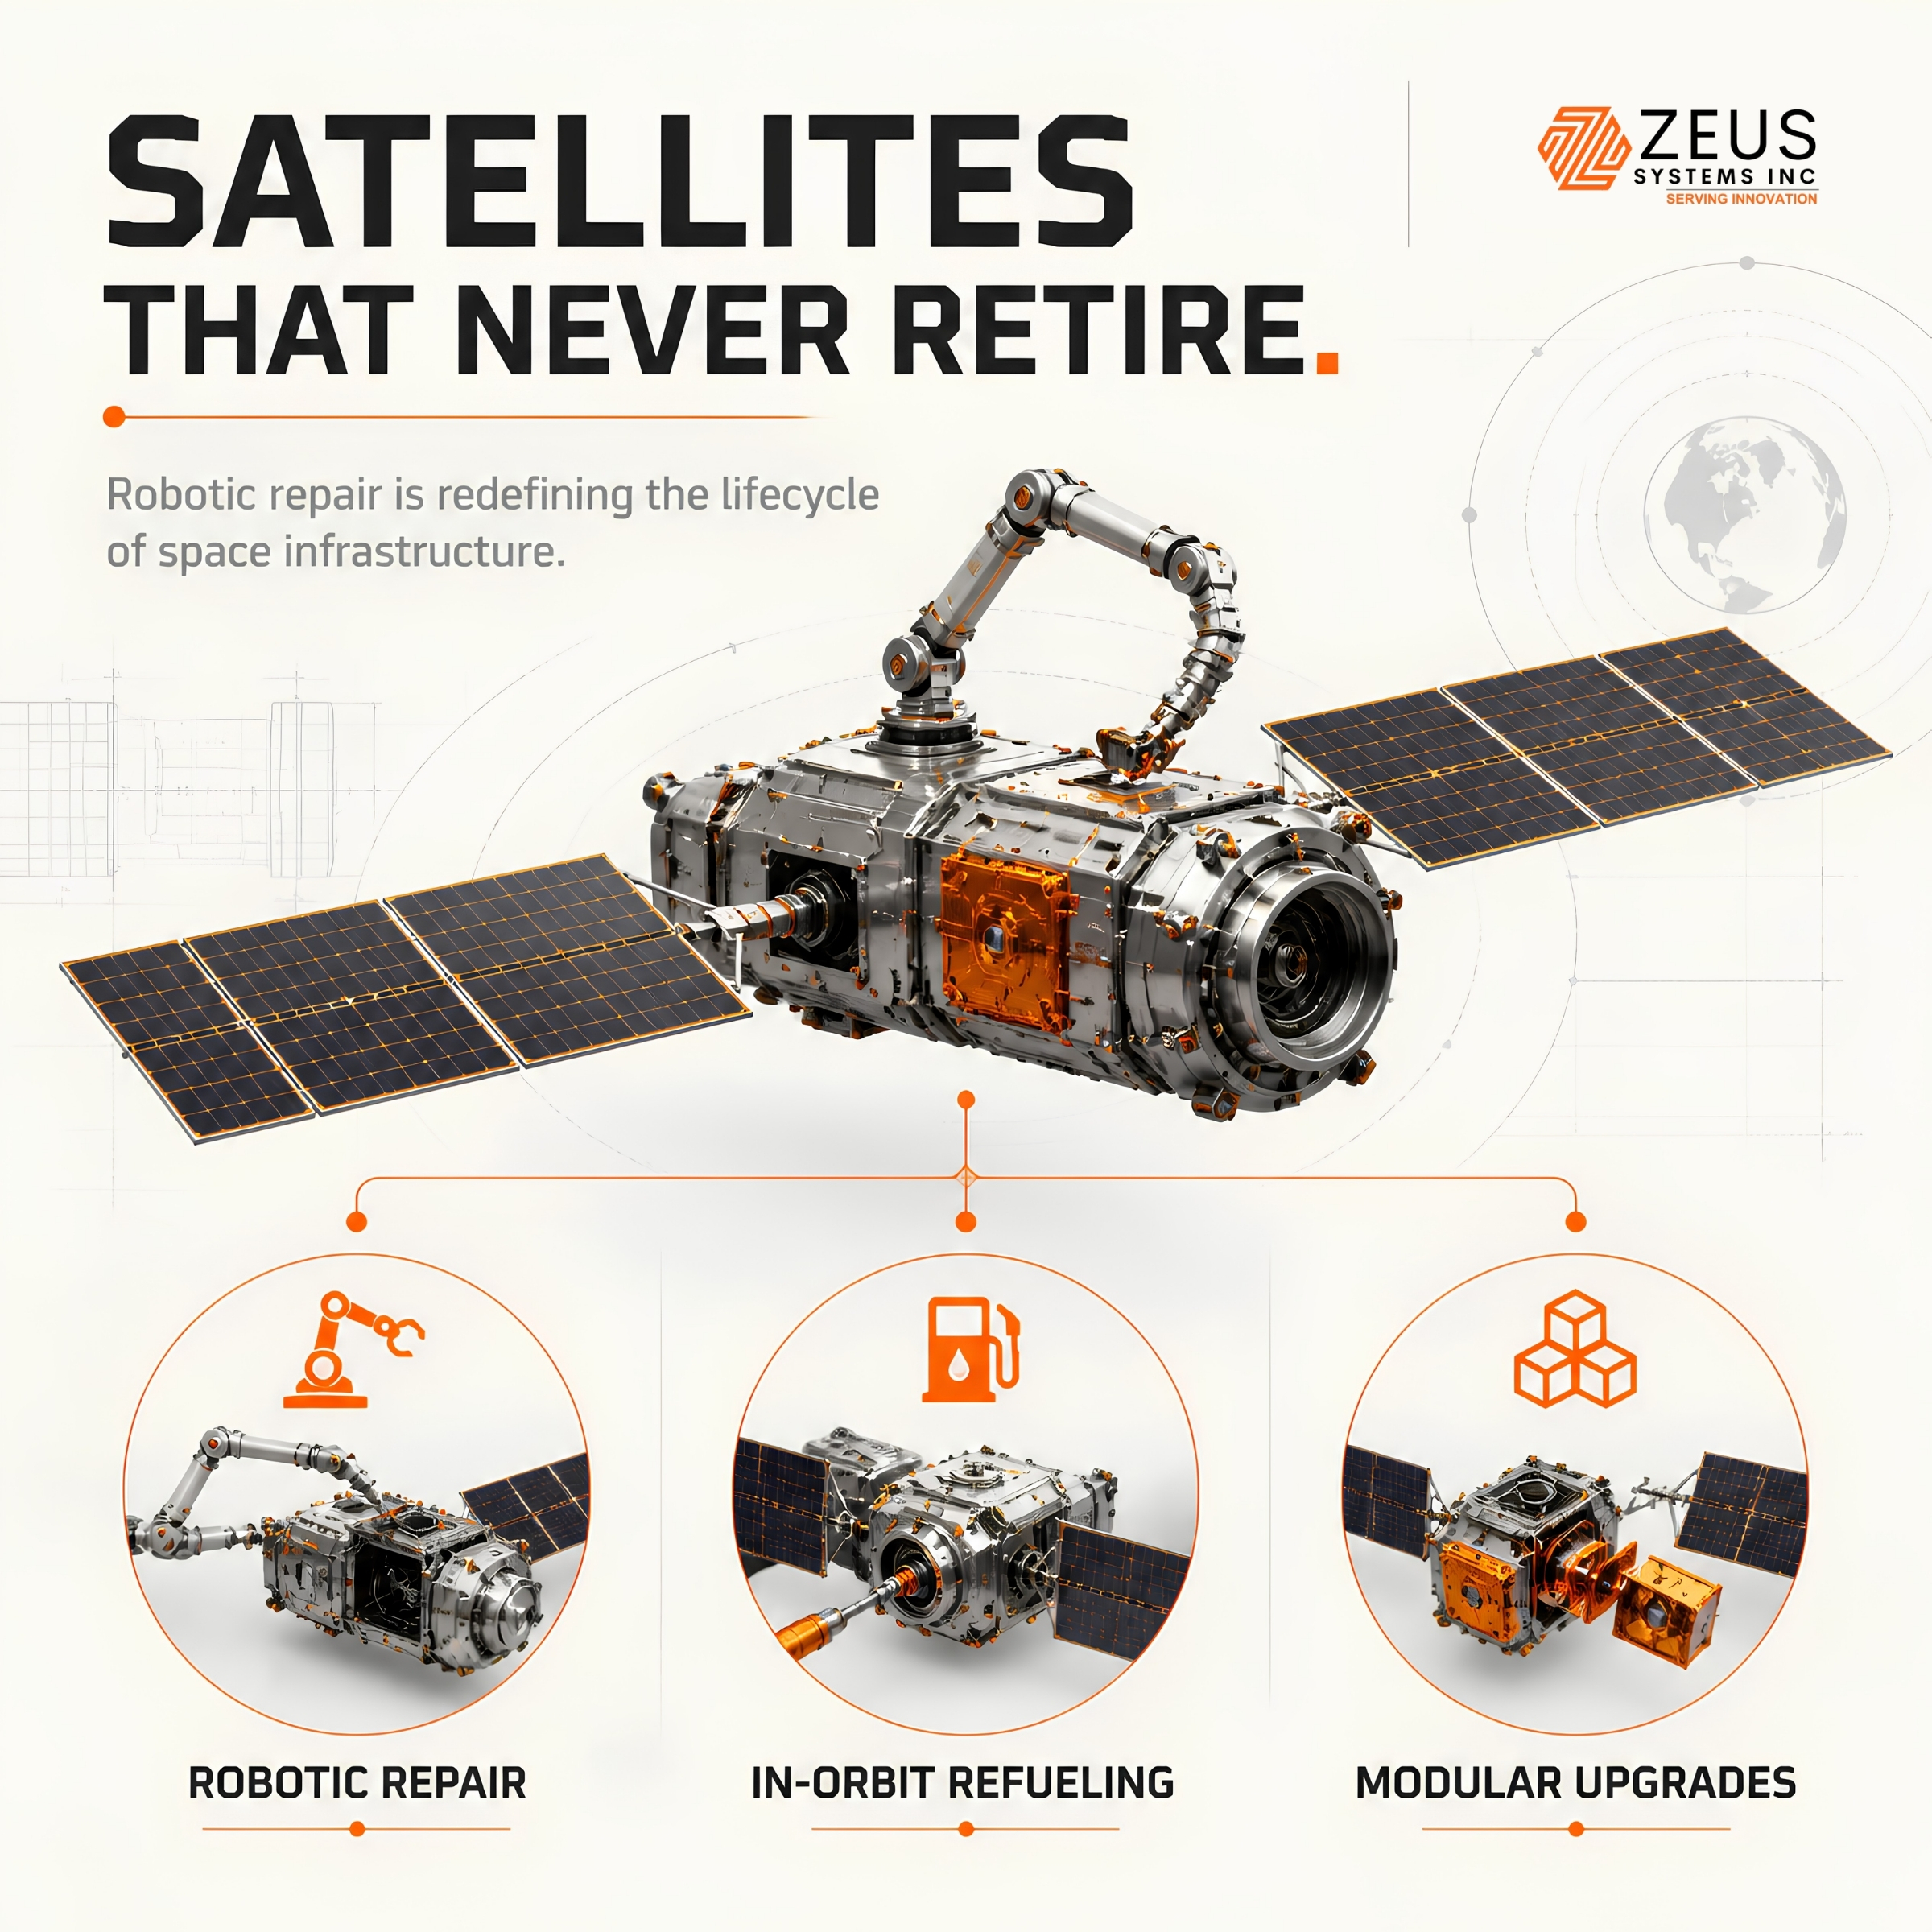
Imagine a satellite launched in 2035 experiencing a propulsion failure in 2044. In today’s conventional model, that failure could mean losing a multimillion-dollar asset, disrupting critical services, and accelerating the need for a replacement launch. Now imagine a different outcome: an autonomous robotic spacecraft approaches, inspects the fault, replaces a modular component, replenishes the satellite’s fuel, and installs a more capable communications unit. The satellite returns to service—not as the machine it was at launch, but as a better version of itself.

This is the future of satellite servicing, and it signals a profound change in how humanity builds and operates infrastructure beyond Earth.

For decades, satellites have followed a strangely unforgiving lifecycle: manufacture, launch, operate, run out of fuel or fail, and eventually retire. Even when the payload remains functional, a depleted propulsion system or a single failing component can compromise an otherwise valuable spacecraft. The economics of space have rewarded launching replacements more often than maintaining assets already in orbit.

That logic is beginning to change.

From disposable hardware to living infrastructure

The emerging field of in-space servicing, assembly, and manufacturing is turning orbit into a potential maintenance environment rather than a graveyard for aging technology. Robotic spacecraft can approach satellites, inspect their condition, dock with compatible systems, and—increasingly sophisticated mission architectures—perform interventions that once seemed impossible without astronauts.

The shift is already moving beyond theory. Northrop Grumman’s Mission Extension Vehicles have demonstrated the ability to dock with operational geostationary satellites and provide additional propulsion and attitude control. In July 2026, a new milestone followed: the company’s Mission Robotic Vehicle, carrying DARPA’s robotic servicing technology, launched with three Mission Extension Pods designed to extend satellite operations. The vehicle is intended to support more advanced robotic work, including inspections, anomaly resolution, relocation, and upgrades. Its launch is a beginning, not proof that every repair capability is operational at scale. Sources: DARPA; Northrop Grumman

The deeper opportunity, however, is not simply extending a satellite’s lifespan. It is separating a satellite’s useful life from the lifespan of its original hardware.

A communications satellite could receive a propulsion upgrade without replacing its entire platform. An Earth-observation spacecraft might gain a new processing module that improves how it handles sensor data. A scientific instrument could potentially be recalibrated, supplemented, or replaced while the spacecraft remains in service. These are different levels of technical maturity, but together they point toward a new principle: launch the infrastructure once; improve its capabilities over time.

The orbital mechanic: robots that do more than dock

Refueling is the most intuitive starting point. Satellites frequently retire not because their primary instruments stop working, but because they can no longer maintain their orbit or orientation with the propellant remaining. A robotic servicer that can transfer fuel could turn a hard operational deadline into a manageable maintenance event.

Yet refueling legacy satellites is difficult. Many were never designed with accessible fuel ports, standardized connections, or robotic servicing in mind. Opening valves, manipulating delicate structures, and transferring propellant in microgravity demand precision, specialized hardware, and carefully controlled autonomous operations. NASA’s OSAM-1 project, intended to demonstrate robotic refueling and in-space assembly, was discontinued in 2024 after significant technical, cost, and schedule challenges. That setback matters: it shows that the future of servicing depends not just on sophisticated robots, but on making spacecraft economically and technically serviceable from the start. Source: NASA

The next generation of orbital mechanics will therefore need more than robotic arms. It will need machine vision, reliable relative navigation, fault diagnosis, tool-changing systems, and software capable of operating safely around expensive, fragile assets. In some scenarios, human operators will supervise the mission; in others, onboard autonomy will be essential because communication delays, operational constraints, and the sheer complexity of close-proximity manoeuvres make continuous manual control impractical.

The most transformative development may be the move from one-off rescue missions to reusable servicing platforms. Instead of designing a bespoke spacecraft to save one failing satellite, operators could eventually deploy robotic vehicles with modular tools, standardized interfaces, and mission software that supports multiple clients. Refueling, inspection, repositioning, and selected repairs could become separate services delivered through a shared orbital infrastructure.

That is when satellite maintenance begins to resemble an industry rather than an experiment.

The software update that changes a spacecraft’s future

Hardware repair is only half the story. The more radical possibility is that satellites could become upgradeable systems.

Today’s technology companies understand that a product’s value does not end at launch. Software updates can improve performance, patch vulnerabilities, introduce capabilities, and extend usefulness without replacing the underlying device. Satellites could adopt a related model—but with a critical difference: some improvements require physical intervention, not just a remote software update.

Imagine an orbital servicing platform that combines diagnostics with robotic intervention. It identifies a degraded subsystem, checks whether the satellite’s design supports a replacement, selects the correct tool, and installs a validated module. A new processing unit might enable more sophisticated onboard analytics; a replacement communications component could support a new operating mode; an additional propulsion package could increase mission flexibility.

This suggests a different product architecture: spacecraft designed around replaceable modules, accessible connection points, published servicing interfaces, and software that can verify the identity and compatibility of installed hardware.

The strategic advantage would be significant. Satellite operators could plan upgrades as part of a product roadmap instead of treating launch day as the moment when the hardware configuration becomes effectively permanent. Manufacturers could sell not only spacecraft, but also upgrade packages, maintenance contracts, and guaranteed servicing compatibility.

In that world, the competitive question changes. It is no longer simply, “How capable is this satellite on launch day?” It becomes, “How much better can this satellite become during its operational life?”

electric vehicles

Your Electric Car as a Power Plant: Could Millions of Vehicles Stabilize the Electricity Grid?

The next revolution in energy may not be built on empty land. It may already be parked outside our homes.

Imagine a summer evening at 7:30 p.m. Millions of households switch on their air conditioners, factories are still operating, and solar generation is falling with the setting sun. Electricity demand climbs just as the grid begins losing one of its cheapest sources of daytime power. Traditionally, utilities would respond by activating expensive generators, drawing on stationary batteries, or importing electricity from neighbouring regions.

Now imagine a different response.

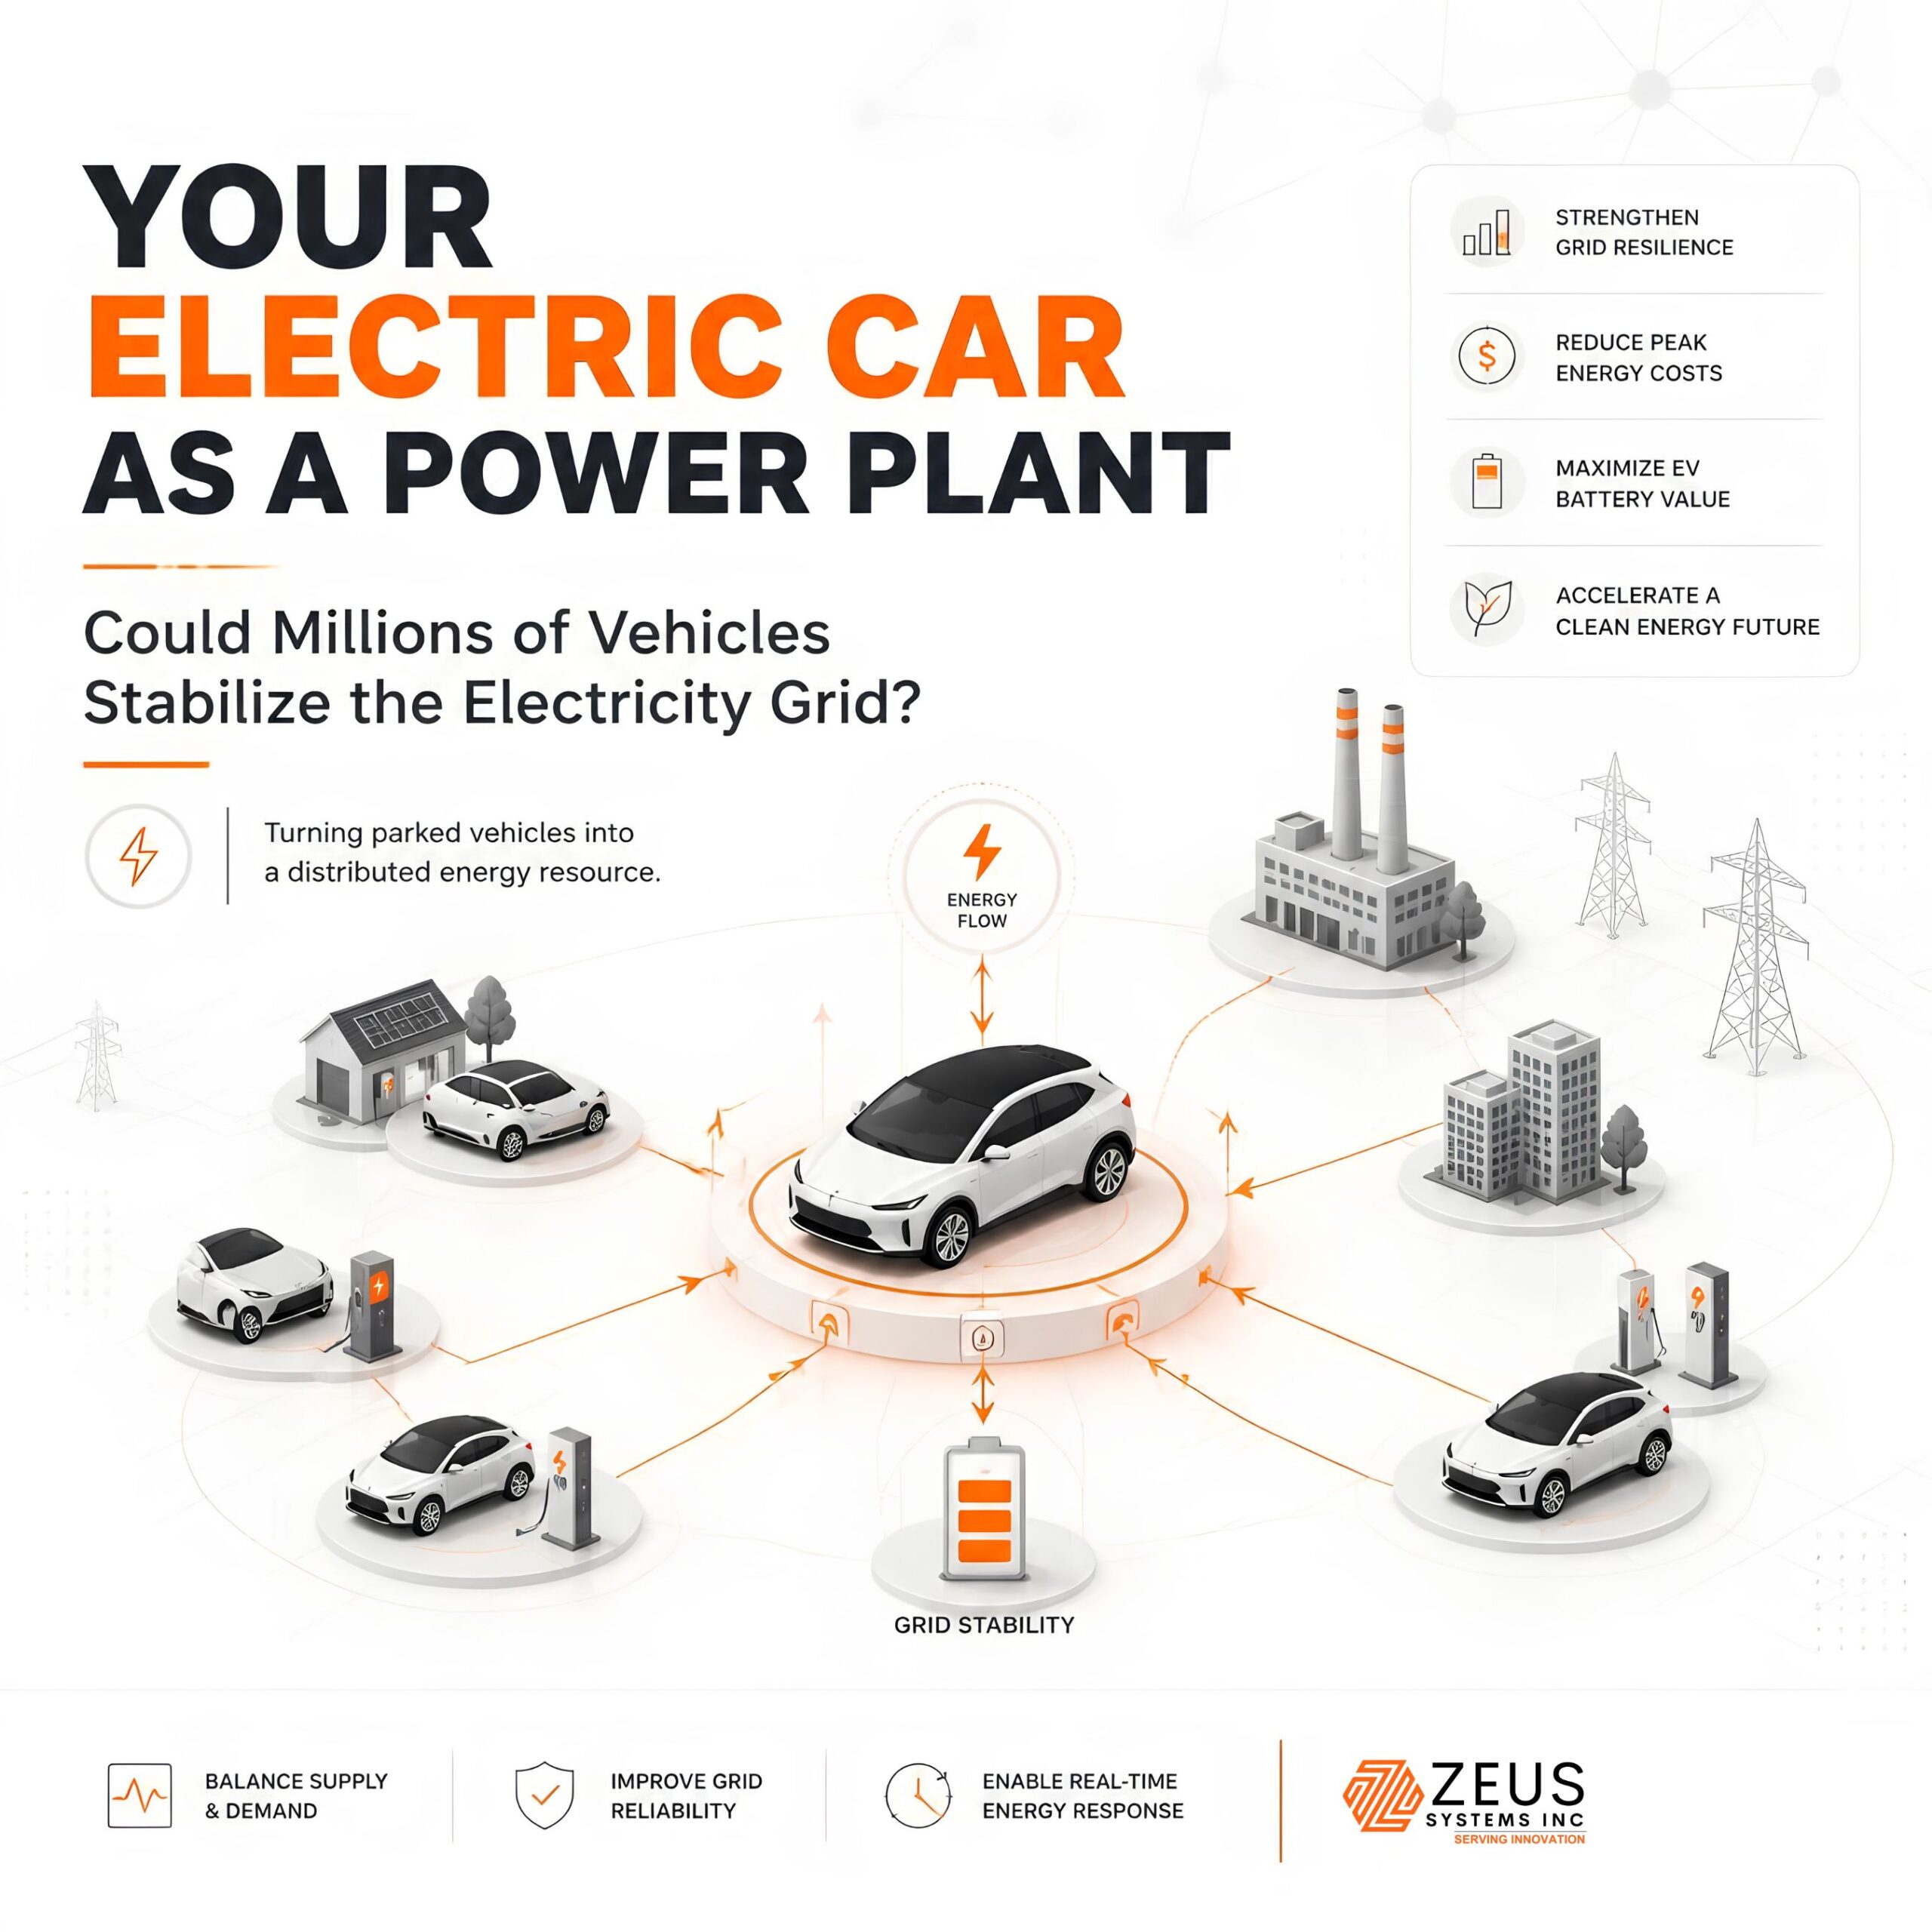
Across the city, thousands of parked electric vehicles quietly release small amounts of stored electricity. A car outside an apartment building contributes 3 kilowatts. Another in a corporate parking lot contributes 5. A fleet of electric taxis, temporarily resting between shifts, supplies additional power. No individual vehicle carries the burden of keeping the lights on. Collectively, however, these vehicles help flatten the demand spike.

The extraordinary part is that the vehicles do not need to become full-time power plants. They need to become intelligent participants in an electricity system that knows when to charge, when to discharge, and when to remain untouched.

This is the emerging promise of vehicle-to-grid technology, or V2G. But its greatest potential lies beyond connecting batteries to power lines. It lies in reimagining the relationship between mobility, electricity, software and ownership.

From Millions of Batteries to One Distributed Power System

An electric vehicle is typically viewed as a machine that consumes electricity to move people and goods. Yet its battery is also a substantial energy-storage asset. When connected to compatible bidirectional charging equipment, it can send electricity back to a building or the grid.

Consider a hypothetical fleet of one million electric vehicles, each equipped with a 60-kWh battery. Their combined nominal storage capacity would be 60 gigawatt-hours (GWh). If only 20% of that fleet were connected, available for grid participation, and able to provide an average of 3 kW each, the fleet could deliver approximately 600 megawatts (MW) of power.

That is a meaningful amount of dispatchable power. It is not, however, a guarantee of 600 MW at every moment, nor does it mean the fleet could sustain that output indefinitely. Actual performance would depend on vehicle availability, battery charge levels, charger capacity, network constraints and drivers’ mobility requirements.

This distinction reveals the real opportunity: the grid does not need access to every battery, all the time. It needs reliable access to enough batteries, in the right places, at the right moments.

The proposed transformation is therefore not simply about connecting vehicles. It is about coordinating their flexibility as a single, distributed resource. Thousands of small, independent decisions—delaying a charge, reducing a charging rate, or releasing a limited amount of stored energy—could become one coordinated response to changing electricity demand.

The International Energy Agency identifies smart charging and V2G as potential tools for reducing peak demand, supporting grid services and limiting some future network investments. The technology is progressing, although commercial availability and interoperability remain significant barriers. IEA, Vehicle-to-grid technology.

The Breakthrough May Be Software, Not Batteries

The most compelling innovation may not be a battery with greater capacity. It may be a software layer that treats connected vehicles as a continuously changing reservoir of energy flexibility.

Consider a hypothetical system called a mobility-aware energy orchestration network. Its purpose would be to coordinate vehicles without compromising the reason they exist: transportation.

Instead of asking, “How much electricity can we extract from these cars?”, the system would ask four more useful questions:

  • Which vehicles are likely to remain parked during the next two hours?
  • How much energy does each driver need before the next departure?
  • Where is electricity most valuable, considering local demand, renewable generation and network congestion?
  • Which vehicles can provide grid support with the least cost, battery wear and disruption to their owners?

The system could then assign different roles to different vehicles. A car expected to leave shortly might pause charging to avoid a local demand spike. A fleet vehicle with several hours before its next shift might discharge a small amount of energy. Vehicles connected near a congested distribution transformer might be scheduled differently from those connected to a network with abundant spare capacity.

This suggests a new design principle: coordinate energy around human mobility, rather than forcing human mobility to accommodate energy management.

The concept could be extended into a distributed flexibility marketplace. Utilities would request a defined amount of power for a particular location and time. Aggregators would assemble eligible vehicles into a virtual power plant, while software would allocate charging and discharging among participants according to availability, price, battery-health limits and driver preferences.

The distinctive opportunity is not that every car becomes a generator. It is that every compatible car becomes a potential, conditional contributor to a larger system.

Can Millions of Vehicles Actually Stabilize the Grid?

The answer depends on what we mean by stabilize.

Electricity grids must balance supply and demand continuously. They also need to maintain acceptable frequency and voltage, avoid overloading equipment, and recover from unexpected disruptions. Coordinated EV charging can help by shifting demand away from constrained periods. Bidirectional vehicles can go further by supplying power and, where suitably equipped and controlled, supporting certain grid services.

But energy capacity and power capacity are different things. A fleet may hold enormous amounts of energy on paper while being unable to deliver it at the moment of greatest need. Many vehicles may be travelling, unplugged, nearly empty or reserved by their owners for emergencies. A fleet concentrated in one neighbourhood cannot automatically resolve a transmission bottleneck elsewhere.

Nor can EV batteries replace every function of conventional generation, transmission infrastructure or stationary storage. They are a flexible resource, not a universal solution.

There is also a financial paradox. Every discharge-and-recharge cycle introduces losses, and additional battery cycling may accelerate degradation. If compensation does not cover electricity costs, conversion losses, equipment expenses and battery wear, drivers may have little reason to participate. Poorly coordinated charging could even create new peaks if millions of vehicles respond to the same price signal simultaneously.

The winning system would therefore need more than an intelligent algorithm. It would require dependable communications, interoperable vehicles and chargers, grid-aware controls, cybersecurity, transparent compensation and enforceable guarantees that drivers retain sufficient charge for their journeys.

The grid must be able to count on the service without assuming it owns the battery.

The Ownership Question: Who Controls the Energy in Your Car?

A more difficult challenge may be social rather than technical.

If an electricity provider can use a privately owned vehicle to support the grid, who decides when the battery discharges? What happens when a driver needs to leave unexpectedly? Who pays for degradation? And can an aggregator change a charging schedule without clearly explaining the financial and practical consequences?

These questions will determine whether V2G becomes mainstream or remains confined to carefully managed pilot projects.

A credible model would begin with driver-defined boundaries: a minimum departure charge, a time by which that charge must be reached, a maximum permitted discharge, and the option to withdraw from grid participation. Compensation would reflect the service provided, while the software would record energy flows and make payments auditable.

Privacy matters equally. An energy-management platform that knows when a car is plugged in, when it leaves, and how much charge it needs can reveal patterns of daily life. Data minimisation, secure authentication and limits on access must be foundational features, not afterthoughts.

In this future, trust becomes part of the infrastructure. A technically perfect system that drivers do not trust will never achieve the participation required to deliver meaningful grid benefits.

The Road Ahead: A Power Plant That Moves

The most realistic path forward is gradual. Smart charging can deliver value even when a vehicle cannot export electricity: charging can be shifted toward periods of abundant renewable generation or lower demand. Bidirectional systems can then add more capabilities where vehicles, chargers, electricity markets and local networks support them.

Commercial deployment will depend on standardisation, grid interconnection rules, viable business models and compatibility across manufacturers. The IEA’s 2026 assessment highlights both the growing potential of V2G and the fact that bidirectional capability and interoperability are still far from universal.

Ultimately, the future electricity system may not be divided neatly into power plants, batteries and consumers. A single electric vehicle could occupy all three roles at different times: a consumer while charging, a storage device while parked, and a source of electricity when conditions permit.

That does not mean millions of vehicles will eliminate blackouts or make conventional power infrastructure unnecessary. It means a resource already being purchased for transportation could also provide a valuable energy service—provided the economics, technology and governance are designed around real human needs.

Perhaps the most consequential shift is this: the next generation of energy infrastructure may not be defined only by what we build, but by how intelligently we coordinate what we already own.

Your electric car may never look like a power plant. Yet, when millions of vehicles become connected, controllable and fairly compensated, the parking lot itself could begin to function like an energy asset.

The question is no longer simply whether a car can return electricity to the grid. It is whether we can build an electricity system intelligent enough to use that capability without compromising the freedom, reliability and trust that make electric mobility valuable in the first place.

Chiplets

The LEGO Computer: Could the Next Supercomputer Be Assembled From Chips Made by Different Companies?

The LEGO Computer: Could the Next Supercomputer Be Assembled From Chips Made by Different Companies?

The future of computing may not belong to the company that builds the biggest processor, but to the ecosystem that learns how to combine the best pieces of silicon.

Imagine designing a supercomputer the way engineers assemble a LEGO structure. One company supplies the computing core. Another contributes ultra-fast memory. A third develops an accelerator optimized for artificial intelligence, while a fourth provides networking or security. Each component is designed independently, manufactured using the process technology best suited to its purpose, and assembled into a single computing system.

Now imagine replacing one component without redesigning the entire machine.

This is not simply a futuristic thought experiment. The semiconductor industry is moving toward a modular approach known as chiplet-based design, and open interconnect standards are beginning to make cross-vendor integration more practical. The more radical possibility is what comes next: computing systems that can be composed from specialized silicon supplied by multiple companies, much as modern software applications are assembled from reusable services and libraries.

The question is no longer whether a processor can contain multiple pieces of silicon. It is whether those pieces can eventually become a truly interoperable hardware ecosystem.

From one giant chip to a silicon ecosystem

For decades, the dominant ambition in semiconductor engineering was to integrate more transistors onto a single piece of silicon. This approach produced extraordinary gains, but advanced manufacturing has become increasingly expensive and technically demanding. Large chips can be difficult to manufacture economically, and not every component benefits equally from the newest fabrication process.

A processor’s computing cores may require cutting-edge transistors, while its input/output circuits, analog components, or certain memory functions may work better on different technologies.

Chiplets offer another approach. Instead of designing every function into one monolithic die, engineers divide a system into smaller dies that communicate inside a shared package. This allows designers to combine different functions and, where practical, different manufacturing processes.

The crucial next step is multi-vendor interoperability.

Today, a chiplet-based system can still depend heavily on components designed to work together by a single company or a tightly coordinated group of suppliers. A genuinely open ecosystem would allow an integrator to select compatible components from a wider market, validate their behavior, and combine them without having to reinvent the entire architecture for each product.

The Universal Chiplet Interconnect Express (UCIe) standard is one important part of this transition. It defines a standardized die-to-die interface and related protocol layers intended to enable chiplet integration across vendors. Its specifications have expanded to address performance, packaging, testing, and system manageability. Meanwhile, the Open Compute Project’s Open Chiplet Economy initiative is explicitly working on the broader challenges of multi-vendor integration.

These are real industry efforts—not proof that arbitrary chips can already be mixed and matched like toy bricks. But they provide a foundation for a different way of building computers.

What if hardware became modular like software?

Consider an AI supercomputer designed to train and run large models.

Rather than committing to one fixed processor architecture, a system designer could theoretically combine general-purpose computing chiplets from one supplier, specialized AI compute dies from another, memory-related components from a third, and connectivity or security functions from others.

A healthcare company might favor accelerators optimized for medical imaging. An industrial robotics company might prioritize low-latency inference and deterministic control. A scientific research laboratory might need high-throughput numerical computing.

The underlying philosophy would be similar: build the hardware around the workload instead of forcing every workload to fit the same hardware.

This could reshape the economics of computing. Smaller semiconductor design companies might contribute specialized chiplets without having to manufacture a complete processor. Cloud providers could differentiate their infrastructure through custom combinations of components. Hardware developers might compete on individual functions rather than having to own the entire technology stack.

The most consequential shift would be from selling finished processors to participating in a silicon ecosystem.

In that world, a chiplet could become a reusable commercial asset: designed by one organization, manufactured by another, integrated by a third, and deployed in systems serving entirely different industries.

But unlike software libraries, silicon components cannot simply be downloaded, connected, and expected to work. Their physical behavior matters. Data must move between dies with extremely low latency and acceptable energy consumption. Power delivery, heat dissipation, manufacturing yield, packaging geometry, and timing all affect whether a combination works.

A standard interface can make communication more predictable. It cannot automatically guarantee that two independently designed components will deliver optimal performance when placed together.

The real breakthrough may be a marketplace for silicon

The most disruptive outcome may not be a single supercomputer. It may be an entirely new way to develop and commercialize hardware.

Imagine a future in which a company can browse a catalog of certified chiplets, select components for a specific workload, and use automated design tools to evaluate compatible combinations before manufacturing begins. A new AI architecture could be introduced by replacing an accelerator chiplet rather than redesigning an entire processor. A security-sensitive application could select a different hardware security component. An industrial system could use a specialized chiplet built for real-time control.

This is a potential silicon marketplace, not an established plug-and-play retail model.

For it to work, the industry would need more than compatible electrical interfaces. It would need trusted specifications, reusable verification models, standardized performance descriptions, reliable manufacturing records, and predictable licensing arrangements. Designers would need to know not only whether a component connects, but also whether it performs as advertised under realistic workloads.

Security is particularly important. If components come from different suppliers, how can a system verify their identities, firmware, provenance, and integrity? Could a malicious or counterfeit chiplet compromise an otherwise trustworthy system? How should vulnerabilities be disclosed when several companies share responsibility for one package?

These are not peripheral concerns. They are fundamental requirements for a multi-vendor hardware ecosystem. The Open Compute Project’s Chiplet Systems workstream explicitly identifies security, performance, power efficiency, system architecture, and interoperability testing as challenges that must be addressed.

Why the LEGO analogy has limits

A LEGO brick is designed to fit predictably with another brick. Semiconductor components are considerably less forgiving.

Two chiplets may implement a compatible interface yet differ in memory behavior, power requirements, timing, thermal characteristics, or software support. Integrating them may require extensive engineering and validation. A design that works with one combination of components may not work with another.

There is also an economic question. Advanced packaging is complex, and moving data between separate dies consumes energy. A modular design is not automatically faster, cheaper, or more efficient than a well-designed monolithic processor. The benefits depend on the workload, the packaging technology, manufacturing yields, and the maturity of the ecosystem.

This is why the next major milestone should not simply be another announcement of a faster interconnect. It should be evidence that independently developed chiplets can be integrated repeatedly, securely, and economically—with substantially less bespoke engineering than is required today.

The next computer may be an ecosystem, not a product

The semiconductor industry’s direction suggests a provocative possibility: the long-term competitive advantage in computing may shift from owning every component to orchestrating the best combination of components.

That would not eliminate the importance of processor architecture, fabrication technology, or integrated design. It would add another dimension to competition: the ability to build reliable systems from independently developed silicon.

For cloud infrastructure, this could enable more workload-specific hardware. For startups, it could lower some barriers to entering specialized computing markets. For enterprises, it could create more flexibility in supplier selection—provided compatibility, long-term availability, and security can be guaranteed.

The implications extend beyond supercomputers. Autonomous vehicles, industrial robots, medical devices, telecommunications equipment, and edge AI systems could all benefit from more modular hardware architectures, although each would face its own certification and reliability requirements.

The LEGO computer, therefore, is not a claim that the industry has solved modular silicon. It is a vision of what could become possible when standardized interfaces, advanced packaging, automated verification, and trusted component supply chains mature together.

The defining question is not whether different companies can manufacture different pieces of a computer. They already can. It is whether the industry can make those pieces interchangeable enough that innovation no longer requires every company to reinvent the entire machine.

If that future arrives, the next computing revolution may not come from one company building the ultimate chip. It may come from thousands of specialized designs becoming useful together.The future of computing may not belong to the company that builds the biggest processor, but to the ecosystem that learns how to combine the best pieces of silicon.

Imagine designing a supercomputer the way engineers assemble a LEGO structure. One company supplies the computing core. Another contributes ultra-fast memory. A third develops an accelerator optimized for artificial intelligence, while a fourth provides networking or security. Each component is designed independently, manufactured using the process technology best suited to its purpose, and assembled into a single computing system.

Now imagine replacing one component without redesigning the entire machine.

This is not simply a futuristic thought experiment. The semiconductor industry is moving toward a modular approach known as chiplet-based design, and open interconnect standards are beginning to make cross-vendor integration more practical. The more radical possibility is what comes next: computing systems that can be composed from specialized silicon supplied by multiple companies, much as modern software applications are assembled from reusable services and libraries.

The question is no longer whether a processor can contain multiple pieces of silicon. It is whether those pieces can eventually become a truly interoperable hardware ecosystem.

From one giant chip to a silicon ecosystem

For decades, the dominant ambition in semiconductor engineering was to integrate more transistors onto a single piece of silicon. This approach produced extraordinary gains, but advanced manufacturing has become increasingly expensive and technically demanding. Large chips can be difficult to manufacture economically, and not every component benefits equally from the newest fabrication process.

A processor’s computing cores may require cutting-edge transistors, while its input/output circuits, analog components, or certain memory functions may work better on different technologies.

Chiplets offer another approach. Instead of designing every function into one monolithic die, engineers divide a system into smaller dies that communicate inside a shared package. This allows designers to combine different functions and, where practical, different manufacturing processes.

The crucial next step is multi-vendor interoperability.

Today, a chiplet-based system can still depend heavily on components designed to work together by a single company or a tightly coordinated group of suppliers. A genuinely open ecosystem would allow an integrator to select compatible components from a wider market, validate their behavior, and combine them without having to reinvent the entire architecture for each product.

The Universal Chiplet Interconnect Express (UCIe) standard is one important part of this transition. It defines a standardized die-to-die interface and related protocol layers intended to enable chiplet integration across vendors. Its specifications have expanded to address performance, packaging, testing, and system manageability. Meanwhile, the Open Compute Project’s Open Chiplet Economy initiative is explicitly working on the broader challenges of multi-vendor integration.

These are real industry efforts—not proof that arbitrary chips can already be mixed and matched like toy bricks. But they provide a foundation for a different way of building computers.

What if hardware became modular like software?

Consider an AI supercomputer designed to train and run large models.

Rather than committing to one fixed processor architecture, a system designer could theoretically combine general-purpose computing chiplets from one supplier, specialized AI compute dies from another, memory-related components from a third, and connectivity or security functions from others.

A healthcare company might favor accelerators optimized for medical imaging. An industrial robotics company might prioritize low-latency inference and deterministic control. A scientific research laboratory might need high-throughput numerical computing.

The underlying philosophy would be similar: build the hardware around the workload instead of forcing every workload to fit the same hardware.

This could reshape the economics of computing. Smaller semiconductor design companies might contribute specialized chiplets without having to manufacture a complete processor. Cloud providers could differentiate their infrastructure through custom combinations of components. Hardware developers might compete on individual functions rather than having to own the entire technology stack.

The most consequential shift would be from selling finished processors to participating in a silicon ecosystem.

In that world, a chiplet could become a reusable commercial asset: designed by one organization, manufactured by another, integrated by a third, and deployed in systems serving entirely different industries.

But unlike software libraries, silicon components cannot simply be downloaded, connected, and expected to work. Their physical behavior matters. Data must move between dies with extremely low latency and acceptable energy consumption. Power delivery, heat dissipation, manufacturing yield, packaging geometry, and timing all affect whether a combination works.

A standard interface can make communication more predictable. It cannot automatically guarantee that two independently designed components will deliver optimal performance when placed together.

The real breakthrough may be a marketplace for silicon

The most disruptive outcome may not be a single supercomputer. It may be an entirely new way to develop and commercialize hardware.

Imagine a future in which a company can browse a catalog of certified chiplets, select components for a specific workload, and use automated design tools to evaluate compatible combinations before manufacturing begins. A new AI architecture could be introduced by replacing an accelerator chiplet rather than redesigning an entire processor. A security-sensitive application could select a different hardware security component. An industrial system could use a specialized chiplet built for real-time control.

This is a potential silicon marketplace, not an established plug-and-play retail model.

For it to work, the industry would need more than compatible electrical interfaces. It would need trusted specifications, reusable verification models, standardized performance descriptions, reliable manufacturing records, and predictable licensing arrangements. Designers would need to know not only whether a component connects, but also whether it performs as advertised under realistic workloads.

Security is particularly important. If components come from different suppliers, how can a system verify their identities, firmware, provenance, and integrity? Could a malicious or counterfeit chiplet compromise an otherwise trustworthy system? How should vulnerabilities be disclosed when several companies share responsibility for one package?

These are not peripheral concerns. They are fundamental requirements for a multi-vendor hardware ecosystem. The Open Compute Project’s Chiplet Systems workstream explicitly identifies security, performance, power efficiency, system architecture, and interoperability testing as challenges that must be addressed.

Why the LEGO analogy has limits

A LEGO brick is designed to fit predictably with another brick. Semiconductor components are considerably less forgiving.

Two chiplets may implement a compatible interface yet differ in memory behavior, power requirements, timing, thermal characteristics, or software support. Integrating them may require extensive engineering and validation. A design that works with one combination of components may not work with another.

There is also an economic question. Advanced packaging is complex, and moving data between separate dies consumes energy. A modular design is not automatically faster, cheaper, or more efficient than a well-designed monolithic processor. The benefits depend on the workload, the packaging technology, manufacturing yields, and the maturity of the ecosystem.

This is why the next major milestone should not simply be another announcement of a faster interconnect. It should be evidence that independently developed chiplets can be integrated repeatedly, securely, and economically—with substantially less bespoke engineering than is required today.

The next computer may be an ecosystem, not a product

The semiconductor industry’s direction suggests a provocative possibility: the long-term competitive advantage in computing may shift from owning every component to orchestrating the best combination of components.

That would not eliminate the importance of processor architecture, fabrication technology, or integrated design. It would add another dimension to competition: the ability to build reliable systems from independently developed silicon.

For cloud infrastructure, this could enable more workload-specific hardware. For startups, it could lower some barriers to entering specialized computing markets. For enterprises, it could create more flexibility in supplier selection—provided compatibility, long-term availability, and security can be guaranteed.

The implications extend beyond supercomputers. Autonomous vehicles, industrial robots, medical devices, telecommunications equipment, and edge AI systems could all benefit from more modular hardware architectures, although each would face its own certification and reliability requirements.

The LEGO computer, therefore, is not a claim that the industry has solved modular silicon. It is a vision of what could become possible when standardized interfaces, advanced packaging, automated verification, and trusted component supply chains mature together.

The defining question is not whether different companies can manufacture different pieces of a computer. They already can. It is whether the industry can make those pieces interchangeable enough that innovation no longer requires every company to reinvent the entire machine.

If that future arrives, the next computing revolution may not come from one company building the ultimate chip. It may come from thousands of specialized designs becoming useful together.

tele medicine

The Clinic That Never Closes

How Telemedicine Is Becoming a Living Healthcare System

For decades, healthcare has been organized around a simple unit of time: the appointment.

A patient becomes visible to the healthcare system when they enter a clinic, speak to a physician, undergo a test, or report a symptom. Then the encounter ends—and for the next several days, weeks, or months, the patient’s health largely disappears from the clinician’s field of view.

Telemedicine was supposed to change that.

But much of today’s virtual healthcare has simply moved the appointment from a hospital room to a smartphone screen. The location changed. The fundamental operating model did not.

The next transformation is different.

Healthcare is beginning to move from episodic observation to continuous clinical awareness.

Remote patient monitoring, virtual care infrastructure, connected medical devices, artificial intelligence, and increasingly sophisticated diagnostic models are converging to create something more powerful than a digital clinic: a healthcare system capable of observing the patient between encounters, recognizing meaningful changes, and bringing the right human expertise into the loop at the right moment.

That is where telemedicine becomes genuinely transformative.

From “Virtual Visit” to “Virtual Presence”

The real innovation in telemedicine is not the video call.

It is virtual presence.

A video consultation can tell a physician what a patient looks and sounds like at 10:30 a.m. on Tuesday. Remote monitoring can potentially reveal how that patient’s physiology behaves over days or weeks.

Blood pressure, glucose, oxygen saturation, heart rhythm, sleep patterns, activity, medication adherence, respiratory patterns and other signals can increasingly become part of a longitudinal clinical picture.

The World Health Organization distinguishes telemedicine from the broader telehealth ecosystem, which can include remote monitoring, diagnostics, education and administrative functions. WWorld Health Organization

The significance of this distinction is easy to underestimate.

A virtual appointment is an event.

A connected healthcare system is a process.

That difference could redefine the patient journey.

Imagine a heart-failure patient whose weight rises subtly over several days. No single measurement may appear catastrophic. But an intelligent system combining weight trends, heart rate, oxygen saturation, medication information and symptom reports could identify a pattern that deserves clinical attention before the patient arrives in an emergency department.

The system does not need to “replace the doctor.”

It needs to make sure the doctor sees the right patient before the situation becomes harder to treat.

That is a much more meaningful definition of remote care.

The New Diagnostic Layer: AI That Watches for Change

The most interesting role for AI in virtual healthcare may not be answering patients’ questions.

It may be detecting change that humans cannot continuously watch for.

Modern healthcare produces enormous quantities of data, but data volume does not automatically create clinical intelligence. In fact, more data can create more noise.

The breakthrough will come from systems that distinguish:

signal from noise, change from variation, and urgency from anxiety.

AI-enabled medical devices are already being used across areas such as medical imaging, disease detection, diagnostic support, risk assessment and physiological monitoring. The U.S. FDA reported more than 1,600 authorized AI-enabled medical devices as of September 2026, illustrating how rapidly AI is moving from experimentation toward regulated clinical use. UU.S. Food and Drug Administration+1

But the future should not be imagined as an omniscient algorithm sitting behind a patient’s phone.

A safer and more realistic architecture is AI as a clinical sensing and prioritization layer.

The AI observes thousands of data points.

It identifies the unusual.

It explains why the unusual matters.

It assigns an appropriate level of confidence.

And then it routes the case to a human.

That creates a new clinical division of labor:

Machines monitor continuously.
AI interprets patterns.
Clinicians exercise judgment.
Patients remain decision-makers in their own care.

That is potentially more powerful than trying to automate the entire healthcare encounter.

Remote Monitoring Needs to Become “Remote Understanding”

There is, however, a major trap.

Putting a wearable on a patient does not automatically create better healthcare.

A 2025 overview of systematic reviews found that evidence for clinical benefits of remote patient monitoring remains limited or difficult to establish across many patient groups. Other recent evidence suggests RPM may reduce hospitalization in some populations, but the certainty of evidence varies considerably. PPubMed Central (PMC)+1

This is an important reality check.

The industry has spent years asking:

“Can we collect the data?”

The more important question is:

“Can we turn the data into an appropriate clinical action?”

That requires a fundamentally different product philosophy.

A next-generation RPM platform should not merely display 2,000 readings on a dashboard. It should construct a dynamic patient state.

Instead of:

Blood pressure: 148/92

the system should eventually be capable of reasoning in a more clinically useful direction:

Blood pressure has progressively increased over six days, coinciding with reduced activity and a change in reported medication adherence. Pattern is outside the patient’s recent baseline. Clinical review recommended.

The distinction is enormous.

One is telemetry.

The other is clinical context.

The Emergence of the “Digital Clinical Twin”

This convergence points toward a concept that could become one of the defining ideas of future virtual healthcare: the digital clinical twin.

Not a perfect digital copy of a human being.

Rather, a continuously updated computational representation of the patient’s health trajectory.

It could combine:

  • Medical history and previous diagnoses
  • Current medications and treatment responses
  • Laboratory and imaging results
  • Wearable and connected-device signals
  • Patient-reported symptoms
  • Behavioral and lifestyle patterns
  • Previous clinical encounters
  • Relevant environmental or contextual factors
  • AI-generated risk assessments

The objective would not be to predict everything that happens to a patient.

It would be to understand what is changing.

A digital clinical twin could establish an individualized baseline and continuously ask:

Is this patient behaving like themselves?

That question is surprisingly powerful.

Healthcare traditionally compares people against population averages. Tomorrow’s virtual healthcare could increasingly compare an individual against their own physiological history.

The patient becomes the baseline.

The AI Doctor Should Not Be the Destination

This is where healthcare must resist technological hype.

The goal should not be to build an AI that impersonates a physician.

Medicine is not simply a classification problem. Diagnosis involves uncertainty, context, ethics, patient preferences, competing risks and consequences that may not be represented in a dataset.

The more promising model is AI-augmented medicine.

AI can summarize a patient’s longitudinal history before a consultation.

It can flag subtle deterioration.

It can compare current imaging with previous studies.

It can identify potential medication interactions.

It can surface relevant clinical evidence.

It can generate differential considerations.

But the clinician remains accountable for deciding what those signals mean in the context of an actual human being.

Regulation is moving in this direction as well. The FDA’s recent guidance and ongoing work emphasize lifecycle management, transparency, bias, monitoring and the performance of AI-enabled medical devices after deployment—not simply whether a model performs well during development. 

biology engineering

Bio-Hypothesis Engines: AI Designing Proteins Nature “Forgot”

Beyond Prediction: When Artificial Intelligence Becomes Biology’s Creative Partner

For decades, computational biology pursued a singular objective: understand nature. Machine learning accelerated that mission by decoding genomes, predicting protein structures, identifying biomarkers, and discovering drug candidates. Yet a more profound transition is emerging—one that shifts artificial intelligence from interpretation to invention.

This transition is not merely about generating new protein sequences. It represents the birth of what may eventually become Bio-Hypothesis Engines: AI systems capable of proposing entirely new biological possibilities that evolution never explored—not because they were impossible, but because natural selection never encountered the environmental pressures necessary to discover them.

Unlike conventional generative AI, which creates text or images by recombining existing patterns, Bio-Hypothesis Engines operate inside the probabilistic design space of molecular reality. Their objective is not creativity for its own sake but functional innovation constrained by physics, chemistry, cellular machinery, and therapeutic outcomes.

This article introduces the Bio-Hypothesis Engine as a conceptual framework rather than an established scientific category. It explores how future AI systems could transform biology from a discipline that observes evolution into one that collaborates with it.

Biology’s Hidden Library

Earth has hosted life for approximately four billion years.

During this immense timescale, evolution produced astonishing molecular diversity:

  • antibodies capable of recognizing billions of antigens
  • enzymes that digest plastic
  • bacteria surviving nuclear reactors
  • proteins producing light
  • molecular motors operating with nanometer precision

Yet this richness hides an uncomfortable truth.

Evolution is extraordinarily creative—but also extraordinarily constrained.

Natural selection only discovers solutions that improve reproductive fitness within local environments.

Evolution never asked questions such as:

  • Could a protein absorb excess inflammatory signals before autoimmune damage begins?
  • Could an enzyme temporarily reverse cellular aging after trauma?
  • Could molecular switches dynamically repair DNA damage before mutations accumulate?
  • Could proteins self-destruct after completing therapy to eliminate long-term toxicity?

Nature did not reject these ideas.

Nature simply never needed them.

The unexplored biological design space remains unimaginably vast.

From Protein Prediction to Protein Imagination

Artificial intelligence has already transformed structural biology.

The first wave focused on prediction.

Input:

Existing amino acid sequence.

Output:

Predicted three-dimensional structure.

The second wave focused on generation.

Input:

Desired biological function.

Output:

Novel protein candidates.

The third wave—which may define the coming decade—is fundamentally different.

Instead of asking,

“Generate a protein.”

Researchers could ask,

“What biological principle would solve this disease?”

The distinction appears subtle.

It is revolutionary.

Rather than optimizing sequences, AI begins designing biological hypotheses.

Introducing the Bio-Hypothesis Engine

A Bio-Hypothesis Engine is envisioned as an AI architecture that reasons simultaneously across multiple biological layers:

  • molecular physics
  • protein folding
  • metabolic pathways
  • gene regulation
  • immune interactions
  • evolutionary dynamics
  • clinical outcomes

Instead of predicting what proteins exist, it asks:

“What proteins should exist?”

The output is no longer merely a sequence.

It becomes an experimentally testable biological theory.

For example:

Current AI:

Protein X may bind receptor Y.

Bio-Hypothesis Engine:

Introducing a transient calcium-responsive binding loop could suppress chronic inflammation while preserving acute immune responses.

Notice the difference.

The second output contains reasoning rather than prediction.

The Concept of Evolutionary Negative Space

Artists often describe negative space as the invisible shape surrounding an object.

Biology possesses its own version.

Imagine every theoretically stable protein represented as a point within an astronomical multidimensional landscape.

Evolution explored only a tiny fraction.

The unexplored remainder forms what can be called Evolutionary Negative Space.

Bio-Hypothesis Engines search this territory.

Instead of copying nature, they investigate molecular possibilities untouched by evolutionary history.

Some regions may prove unstable.

Others may outperform naturally evolved proteins for modern medical challenges.

Cancer, Alzheimer’s disease, autoimmune disorders, radiation injury, and synthetic pathogens represent selective pressures evolution never experienced at scale.

Human-designed biology therefore need not imitate nature.

It may complement it.

The Rise of Functional Hallucination

Generative AI is famous for hallucinations.

In biology, hallucination carries a different meaning.

Most generated proteins fail.

But failure is not always error.

Some “hallucinated” proteins may represent biologically valid structures that simply never existed before.

Instead of filtering out every novel prediction, future research may classify hallucinations into three categories:

Impossible Hallucinations

Violating chemistry or thermodynamics.

Neutral Hallucinations

Stable proteins lacking measurable function.

Functional Hallucinations

Entirely novel proteins performing valuable biological tasks.

Ironically, tomorrow’s blockbuster therapies may originate from today’s rejected hallucinations.

CRISPR Becomes a Design Language

CRISPR revolutionized gene editing by providing molecular precision.

Its next evolution may be semantic rather than mechanical.

Future AI systems could treat CRISPR not merely as molecular scissors but as a programmable biological language.

Instead of editing one mutation, AI could coordinate hundreds of synchronized edits while anticipating downstream effects across tissues.

Imagine describing therapy in natural language:

“Restore insulin regulation without increasing cancer risk.”

The Bio-Hypothesis Engine translates that objective into:

  • genomic edits
  • protein engineering
  • regulatory RNAs
  • epigenetic modifications
  • immune compatibility strategies

Biology becomes programmable at the level of intent.

Digital Evolution Without Geological Time

Natural evolution is slow because every experiment requires living organisms.

AI eliminates much of that limitation.

Millions of virtual evolutionary cycles may eventually occur before a single laboratory experiment begins.

Each simulated generation learns from:

  • molecular dynamics
  • structural stability
  • metabolic efficiency
  • toxicity prediction
  • immunogenicity
  • evolutionary robustness

The laboratory increasingly validates intelligence rather than discovering it.

Undruggable Diseases May Actually Be Undesigned Diseases

Medicine frequently labels disorders as “undruggable.”

That terminology reflects technological limits more than biological impossibility.

Many diseases resist treatment because conventional pharmaceuticals interact with static molecular targets.

Living systems are dynamic.

Bio-Hypothesis Engines could instead design adaptive therapeutics capable of changing configuration according to cellular context.

Imagine proteins that:

activate only inside tumors

become inactive in healthy tissue

self-degrade after completing treatment

communicate with immune cells

repair mutations before disease symptoms emerge

The challenge shifts from finding drugs to designing biological behaviors.

The Closed-Loop Biology Laboratory

Future biological research may resemble autonomous engineering.

An iterative cycle emerges:

AI proposes hypotheses.

Robotic laboratories synthesize molecules.

Automated experiments generate observations.

Machine learning refines biological understanding.

The updated model proposes better hypotheses.

Each cycle compresses months of research into days.

Discovery itself becomes recursive.

Measuring Biological Originality

One overlooked challenge is evaluating novelty.

Existing AI benchmarks emphasize accuracy.

Bio-Hypothesis Engines require different metrics.

Possible future measures include:

Evolutionary Distance Index

How far the proposed molecule deviates from known biological families while remaining functional.

Functional Originality Score

Whether the protein performs tasks absent from existing biology.

Repair Complexity Reduction

The number of biological pathways simplified by the intervention.

Adaptive Stability

Performance across genetically diverse populations.

Originality becomes scientifically measurable rather than philosophically debated.

Biological Compression

Perhaps the deepest implication concerns information itself.

Proteins represent compressed knowledge.

Every amino acid sequence encodes billions of years of evolutionary experimentation.

Bio-Hypothesis Engines reverse this process.

Instead of extracting information from evolution, they compress scientific understanding into entirely new molecular architectures.

Knowledge becomes biology.

Ideas become proteins.

Reasoning becomes medicine.

Scientific and Ethical Boundaries

The transformative potential of Bio-Hypothesis Engines is inseparable from significant responsibility. Designing novel proteins or CRISPR-based interventions requires rigorous experimental validation, biosafety oversight, regulatory review, and ethical governance. Computational models can suggest promising candidates, but they cannot establish safety or efficacy on their own.

Responsible development should include:

  • transparent documentation of AI-generated hypotheses
  • reproducible laboratory validation
  • independent safety assessments
  • secure handling of sensitive biological data
  • multidisciplinary oversight spanning biology, medicine, ethics, and public policy

Progress in generative biology will depend not only on more capable AI, but also on stronger frameworks for evaluating and governing its outputs.

The Next Scientific Revolution

Artificial intelligence has already transformed software by generating code.

It transformed language by generating text.

It transformed art by generating images.

Its next frontier is more consequential.

Generating biology.

The most important molecules of the next century may not descend from ancient organisms.

They may originate from computational reasoning constrained by chemistry and validated through experimentation.

This possibility does not imply replacing evolution. Rather, it suggests extending humanity’s capacity to explore biological design spaces that natural selection never encountered.

If future AI systems become capable of proposing biologically plausible, experimentally testable hypotheses at scale, the central question of biomedical innovation may evolve from:

“What has nature already discovered?”

to

“What remains biologically possible?”

The emergence of Bio-Hypothesis Engines, if realized responsibly, would mark a profound shift in scientific practice. Biology would no longer be limited to interpreting life’s existing molecular repertoire; it would become a discipline that systematically explores new, evidence-driven possibilities for healing disease. In that future, the greatest medical breakthrough may not be a single drug or protein. It may be the creation of an intelligence that continuously expands the boundaries of biology itself—one experimentally validated hypothesis at a time.

Superconductors

Pressure-Quenched Superconductors: The Quest for Ambient Electricity

How Pressure Quenching Could Rewrite the Physics of Energy, Computing, and Civilization

Introduction: The Day Electricity Forgot How to Resist

Every civilization has been shaped by its ability to move energy.

The Bronze Age mastered metallurgy.
The Industrial Revolution mastered steam.
The Digital Revolution mastered information.

The next transformation may emerge from something even more fundamental: eliminating electrical resistance itself.

For more than a century, superconductivity has represented one of physics’ most extraordinary phenomena. A superconducting material allows electrical current to travel indefinitely without losing energy as heat. Magnetic fields behave differently. Quantum mechanics reveals itself at a macroscopic scale. Entire technological paradigms become possible.

Yet superconductivity has remained frustratingly impractical.

Nearly every useful superconductor demands either extremely low temperatures, immense mechanical pressure, or both. The engineering costs of maintaining these environments have confined superconductivity largely to laboratories, particle accelerators, MRI scanners, and a handful of specialized industrial applications.

A growing frontier in condensed matter physics, however, has begun challenging this limitation.

Rather than maintaining enormous pressures continuously, researchers are exploring whether pressure can instead be used as a temporary “architect of matter”—forcing atoms into new arrangements that remain stable after the pressure is removed.

This emerging concept is known as pressure quenching.

Instead of treating pressure as an operating requirement, scientists increasingly view it as a manufacturing tool capable of creating metastable superconducting states.

If successful, pressure quenching would fundamentally redefine superconductivity—not by discovering an entirely new physical law, but by changing how superconducting materials are made.

The distinction is subtle.

The consequences are enormous.

Understanding Superconductivity Beyond the Textbook

Electrical resistance is usually described as electrons colliding with atoms.

While accurate, this explanation misses the extraordinary collective behavior inside superconductors.

In ordinary metals, electrons behave as individuals.

Inside superconductors they behave as a synchronized quantum population.

Instead of scattering randomly, electrons form delicate quantum pairs known as Cooper pairs. These pairs move collectively through the crystal lattice, avoiding the scattering events responsible for electrical resistance.

The material effectively becomes one coherent quantum object.

This transition depends upon an intricate balance involving:

  • atomic spacing
  • lattice vibrations
  • electron density
  • quantum interactions
  • crystal symmetry
  • magnetic behavior

Tiny structural changes can completely destroy—or unexpectedly create—superconductivity.

Pressure changes every one of these variables simultaneously.

Why Pressure Matters

Imagine squeezing a sponge.

Its shape changes.

Its internal structure rearranges.

Its properties change.

Crystals behave similarly, except the rearrangements occur at the atomic level.

Applying hundreds of gigapascals of pressure forces atoms closer together than nature normally permits.

Unexpected electronic structures emerge.

New crystal phases appear.

Energy bands reorganize.

Sometimes superconductivity suddenly appears where none previously existed.

Hydrogen-rich compounds have demonstrated superconductivity at temperatures approaching room temperature—but only under pressures rivaling those inside giant planets.

This creates a paradox.

The material itself may already possess extraordinary superconducting capability.

The surrounding environment does not.

Pressure Quenching: Freezing an Impossible State

Pressure quenching asks a deceptively simple question:

Can we remove the pressure without allowing the atoms to return to their original arrangement?

Instead of slowly releasing compression, scientists rapidly reduce pressure under carefully controlled thermal conditions.

The crystal can become trapped inside a metastable configuration.

Think of volcanic glass.

Molten rock normally crystallizes.

Rapid cooling prevents that crystallization.

The liquid structure becomes frozen into solid glass.

Pressure quenching attempts something conceptually similar.

Instead of freezing temperature,

it freezes atomic architecture.

The resulting material occupies a configuration that would ordinarily never exist under ambient conditions.

Metastability: Nature’s Hidden Shelf

The concept of metastability appears throughout nature.

Diamonds exist because carbon remains trapped in a high-pressure structure formed deep within Earth’s mantle.

Given enough time, every diamond should become graphite.

Yet they persist for geological timescales.

Pressure-quenched superconductors seek an analogous state.

Not necessarily the lowest-energy arrangement.

Simply one that refuses to transform.

This distinction changes everything.

The objective is no longer discovering an impossible room-temperature material.

Instead, researchers seek ways to manufacture one.

Pressure as Manufacturing Rather Than Operating Condition

Historically, pressure has functioned like refrigeration.

The material only works while maintained inside specialized equipment.

Pressure quenching transforms pressure into something closer to heat treatment in metallurgy.

Steel becomes stronger after controlled heating and cooling.

The furnace is no longer required afterward.

Likewise, future superconductors might require enormous pressure only during fabrication.

The finished wire, chip, cable, or magnet could operate under ordinary conditions.

Pressure would become part of manufacturing—not infrastructure.

The Rise of Structural Memory

One of the most fascinating ideas emerging from recent studies is structural memory.

Materials sometimes remember arrangements created under extreme environments.

Atomic defects.

Vacancies.

Stacking faults.

Nanoscopic strain.

These imperfections, traditionally considered undesirable, may actually stabilize superconductivity.

Instead of eliminating defects, future materials science may deliberately engineer them.

Imperfection becomes functionality.

Disorder becomes architecture.

Quantum Locking of Crystal Landscapes

Every crystal exists inside an energy landscape.

Picture mountains and valleys.

The deepest valley represents perfect equilibrium.

Pressure pushes the system uphill.

Quenching attempts to drop the material into a different valley before it can roll back.

The superconducting phase may not be the absolute minimum.

It simply needs a sufficiently high energy barrier preventing escape.

The engineering challenge becomes sculpting these barriers.

Superconductivity thus becomes less about chemistry and more about energy-landscape design.

Artificial Pressure Without Pressure

Perhaps the most exciting implication of pressure-quenching research is that physical pressure may eventually become unnecessary.

Scientists are increasingly exploring methods to imitate compression using:

  • epitaxial strain
  • interface engineering
  • lattice mismatch
  • chemical substitution
  • ion implantation
  • nanoscale confinement

These techniques effectively generate internal pressure.

The crystal behaves as though compressed despite existing under ordinary atmospheric conditions.

Pressure becomes encoded into the material itself.

The Future Superconducting Factory

Imagine manufacturing facilities unlike any existing semiconductor fab.

Instead of merely depositing thin films, future plants might sequentially manipulate:

  • pressure
  • magnetic fields
  • electric fields
  • laser pulses
  • ultrafast cooling
  • atomic layer deposition
  • quantum defect engineering

Every production stage shapes the quantum landscape.

The product emerging from the line is not merely a material.

It is a deliberately engineered quantum phase.

Implications for the Energy Grid

Today’s electrical grids lose significant energy during transmission.

Those losses require additional power generation.

Additional fuel.

Additional infrastructure.

Superconducting transmission could nearly eliminate resistive losses over long distances, reduce cable size for a given current, and enable more compact high-capacity systems. The broader impact would depend on manufacturing cost, durability, and deployment challenges.

Instead of building more power plants,

we could waste far less electricity.

Computing Beyond Silicon

Modern processors increasingly struggle with heat rather than computation.

Electrical resistance produces thermal energy.

Thermal energy limits transistor density.

Superconducting electronics promise dramatically lower energy dissipation in certain applications.

Pressure-quenched materials could accelerate:

  • quantum processors
  • superconducting memory
  • cryogenic AI hardware
  • ultra-sensitive sensors
  • ultrafast communication systems

Entire computing architectures might emerge around negligible resistive loss.

Transportation Reinvented

Magnetic levitation trains already demonstrate the potential of superconductivity.

Ambient-pressure superconductors could reduce reliance on complex cooling systems, potentially simplifying future designs.

The implications extend beyond rail.

Electric aircraft.

Heavy cargo transport.

Marine propulsion.

Space launch systems.

Each depends fundamentally upon efficient power handling.

Medicine Without Limits

MRI technology transformed diagnostic medicine through superconducting magnets.

Pressure-quenched superconductors could eventually enable:

  • more affordable scanners
  • portable imaging
  • higher magnetic fields
  • lower operating costs
  • wider global accessibility

Medical innovation often follows material innovation.

Scientific Challenges That Remain

Pressure quenching is promising, but major obstacles remain.

Researchers continue investigating whether metastable superconducting phases can be produced reproducibly, maintained for long periods, manufactured at useful scales, and retain desirable superconducting properties under everyday operating conditions.

Even if one material succeeds,

engineering must solve manufacturing.

Manufacturing must solve economics.

Economics must solve adoption.

History shows these transitions often take decades.

Beyond Superconductivity: Programming Matter

Perhaps the deepest implication of pressure quenching extends beyond superconductors.

It suggests a broader philosophy.

Instead of discovering materials,

we increasingly design histories.

Every pressure cycle…

every temperature pathway…

every nanosecond of cooling…

becomes part of the material’s identity.

Matter acquires memory.

Processing becomes programming.

Physics becomes manufacturing.

This shift may ultimately prove more important than superconductivity itself.

Conclusion: The Quiet Revolution Under Pressure

The pursuit of ambient superconductivity has long resembled a search for a mythical material—one miraculous compound that would solve every challenge at once.

Pressure quenching offers a different vision.

Rather than asking nature to provide a perfect crystal, it asks whether we can guide ordinary materials into extraordinary states and persuade them to stay there.

That idea is both scientifically ambitious and technologically pragmatic. It reframes pressure not as a permanent constraint but as a temporary tool for engineering atomic arrangements that may exhibit remarkable properties after fabrication.

Whether pressure-quenched superconductors ultimately become the foundation of next-generation power grids or remain an important stepping stone toward other breakthroughs, they have already expanded how scientists think about materials. The frontier is no longer limited to discovering new compounds—it includes discovering new pathways through which matter can be transformed.

If the twentieth century taught humanity how to manipulate electrons, the twenty-first may teach us how to sculpt the landscapes through which those electrons move.

The future of electricity may not depend solely on finding a new material.

It may depend on remembering how that material was made.

Cyber Security

Preemptive Cybersecurity: AI That Battles Threats Before They Exist

Beyond Firewalls, Beyond Detection The Rise of Autonomous Defense Intelligence

Abstract

For nearly half a century, cybersecurity has been governed by one flawed assumption:

An attack must exist before it can be defended against.

Every major security technology—from antivirus software to intrusion detection systems, SIEM platforms, endpoint protection, XDR, and even modern AI-assisted SOCs—shares the same DNA. They observe reality, identify anomalies, and respond after evidence appears.

Even “real-time protection” is fundamentally reactive.

But what if cyber defense stopped waiting?

What if artificial intelligence became an autonomous civilization of defenders that continuously invents attacks that have never existed, weaponizes them against itself, discovers vulnerabilities before attackers imagine them, designs countermeasures automatically, validates them, and rewrites its own security posture every hour?

This is not merely predictive cybersecurity.

This is Preemptive Cybersecurity—an entirely new security philosophy where AI continuously manufactures possible futures and defeats them before they become reality.

The firewall becomes obsolete.

Threat intelligence becomes secondary.

Incident response becomes rare.

Instead, organizations evolve into living immune systems that permanently stay ahead of adversaries.

The End of Reactive Security

Today’s cybersecurity resembles medieval city defense.

Walls are built.

Guards watch.

When enemies arrive, defenders respond.

Modern companies simply replaced castles with firewalls.

Instead of walls:

  • Firewalls
  • Antivirus
  • IDS
  • IPS
  • EDR
  • SIEM
  • SOAR
  • Threat Intelligence
  • MDR

They all wait.

They detect.

Then they react.

Even AI-powered SOCs primarily answer one question:

“Something happened. What should we do?”

That mindset guarantees one uncomfortable truth:

Attackers always move first.

Even if defenders respond within seconds…

the attacker already discovered the weakness.

That timing difference creates billion-dollar losses.

A Different Philosophy

Imagine asking AI an entirely different question.

Instead of:

“What attacks are happening?”

Ask:

“What attacks could exist tomorrow?”

That tiny shift changes everything.

Instead of consuming threat intelligence…

AI generates threat intelligence.

Instead of reading CVEs…

AI creates hypothetical CVEs.

Instead of monitoring hackers…

AI becomes the hacker.

Introducing Autonomous Defense Agents

Traditional AI assistants answer questions.

Autonomous Defense Agents pursue missions.

Mission:

Find ways to destroy our infrastructure before criminals do.

Unlike security tools, these agents have independent objectives.

Thousands of specialized AI agents cooperate simultaneously.

Examples include:

Attack Architect Agent

Invents entirely new exploitation techniques.

Never-before-seen privilege escalations.

Novel API abuse.

Cloud-native attacks.

Quantum-inspired cryptographic failures.

Cross-model AI poisoning.

Unknown memory corruption methods.

Attacks nobody has documented.

Infrastructure Twin Agent

Maintains an exact digital replica of production.

Every VM.

Every container.

Every API.

Every IAM policy.

Every network route.

Every database permission.

Every employee role.

The twin updates continuously.

Every infrastructure change instantly appears inside the simulation.

Evolution Agent

Borrowing principles from biological evolution:

Millions of attacks compete.

Weak attacks disappear.

Successful attacks mutate.

Each generation becomes smarter.

Within hours…

AI discovers exploit chains humans might never imagine.

Chaos Engineering Agent

Intentionally creates failures.

Deletes servers.

Revokes certificates.

Corrupts configurations.

Introduces packet loss.

Creates identity failures.

Simulates insider threats.

Launches ransomware.

Executes supply-chain compromises.

Every disaster becomes training.

Defensive Architect Agent

Discovers weaknesses.

Automatically proposes:

  • code changes
  • IAM modifications
  • network redesign
  • infrastructure segmentation
  • secret rotation
  • dependency replacement

Then validates every recommendation through simulation.

Only proven improvements reach production.

Millions of Parallel Universes

Traditional penetration testing explores one reality.

Autonomous Defense explores millions.

Imagine one infrastructure cloned one million times overnight.

Universe 1

A malicious employee steals credentials.

Universe 2

A compromised AI model generates malware.

Universe 3

Quantum decryption becomes practical.

Universe 4

DNS collapses.

Universe 5

A cloud provider experiences regional failure.

Universe 6

A software dependency becomes malicious.

Universe 7

An AI-powered ransomware negotiates automatically.

Universe 8

A language model begins writing polymorphic exploits.

Universe 9

Biometric authentication is spoofed.

Universe 10

Every administrator account becomes compromised simultaneously.

The process continues…

Millions of universes.

Millions of attacks.

Millions of outcomes.

Every morning, the organization awakens having already survived tomorrow’s disasters.

Synthetic Zero-Day Discovery

Current zero-days depend on discovery.

Researchers investigate.

Attackers investigate.

Eventually someone finds one.

Preemptive AI changes the sequence.

Instead of discovering vulnerabilities…

AI manufactures hypothetical software behaviors.

It asks:

“If this compiler optimized differently…”

“If this API cached differently…”

“If this protocol evolved…”

“If memory alignment shifted…”

“If authorization inherited incorrectly…”

“If AI generated insecure code…”

“If hardware timing changed…”

Each hypothetical branch becomes a searchable universe.

Many never happen.

Some become tomorrow’s real vulnerabilities.

When reality eventually reaches that branch…

the defense already exists.

Self-Evolving Digital Immune System

Biological immune systems do not memorize only known viruses.

They continuously generate enormous numbers of antibodies.

Most never become useful.

Some perfectly match future pathogens.

Cybersecurity can adopt the same philosophy.

Autonomous AI continuously invents defensive strategies.

Billions of virtual antibodies.

Firewall rules.

Identity policies.

Behavioral models.

Kernel protections.

Memory isolation techniques.

Encryption mutations.

Network segmentation strategies.

Most remain unused.

The correct one already exists when needed.

Continuous Security Evolution

Instead of annual penetration tests:

Every second.

Instead of monthly vulnerability scans:

Every minute.

Instead of quarterly audits:

Continuous.

The organization never stops attacking itself.

Security becomes evolution rather than inspection.

The Birth of Security Genetics

Software today has source code.

Imagine security DNA.

Every infrastructure component carries genetic markers describing:

Attack resistance.

Recovery capability.

Trust relationships.

Identity resilience.

Supply-chain exposure.

AI mutates this DNA constantly.

Poor mutations disappear.

Successful mutations spread automatically across the enterprise.

Security becomes hereditary.

Every deployment inherits stronger genetics.

Autonomous Counterfactual Computing

Perhaps the most revolutionary capability is counterfactual reasoning.

Instead of asking:

“What happened?”

AI asks:

“What almost happened?”

“What nearly became catastrophic?”

“What invisible chain barely failed?”

Suppose a developer accidentally commits credentials.

Git blocks the push.

Nothing happens.

Traditional systems ignore it.

Counterfactual AI investigates.

“What if Git failed?”

“What if detection arrived 15 minutes later?”

“What if attackers indexed the repository?”

“What if automated malware harvested the secret?”

Entire attack chains emerge from events that never occurred.

Organizations learn from alternate realities.

Economic Warfare Against Attackers

Cybercrime depends upon return on investment.

Autonomous defense intentionally destroys attacker economics.

Every reconnaissance attempt encounters:

Artificial vulnerabilities.

Synthetic credentials.

Fake databases.

Moving attack surfaces.

Rotating identities.

Morphing APIs.

Dynamic operating systems.

Adaptive binaries.

The environment changes faster than attackers can understand it.

Preparation becomes impossible.

Attack costs skyrocket.

Profits collapse.

Living Infrastructure

Servers stop being static machines.

Applications become living organisms.

Every day:

Routes change.

Secrets rotate.

Authentication evolves.

Containers mutate.

Permissions adapt.

Encryption refreshes.

Architectures reorganize.

Attackers cannot map systems that continuously transform.

AI vs AI Civilization

The future battlefield is not human versus hacker.

It becomes:

Attacker AI

versus

Defender AI.

Both evolve continuously.

One invents attacks.

The other invents defenses.

Neither sleeps.

Neither pauses.

Neither waits.

Cybersecurity becomes autonomous competition between artificial civilizations.

Humans become governors rather than operators.

Measuring the Future Instead of the Past

Traditional security metrics include:

  • Number of attacks blocked
  • Mean Time to Detect (MTTD)
  • Mean Time to Respond (MTTR)
  • Vulnerabilities patched
  • Incidents closed

Preemptive Cybersecurity introduces new measurements:

Future Exposure Index (FEI)

How many plausible attack paths remain unexplored?

Hypothetical Compromise Probability (HCP)

Probability of compromise across simulated futures.

Autonomous Discovery Velocity (ADV)

Rate at which AI discovers new exploit possibilities.

Defense Evolution Rate (DER)

How quickly defensive architectures improve without human input.

Counterfactual Survival Score (CSS)

Percentage of alternate futures in which the organization survives.

Organizations begin measuring resilience against futures—not just history.

The Ethical Dimension

Granting AI the ability to invent attacks raises profound responsibilities.

Strong governance is essential. Any autonomous defense system should operate within strict technical and organizational guardrails:

  • Isolated simulation environments with no direct path to production.
  • Human oversight for high-impact changes.
  • Cryptographic signing and verification of approved defensive updates.
  • Immutable audit trails of every AI-generated recommendation.
  • Clear authorization boundaries that prevent autonomous offensive actions outside the organization’s own systems.
  • Independent validation to ensure defensive changes do not introduce unacceptable operational risk.

The objective is not to create unrestricted offensive AI, but to create continuously improving defensive intelligence that operates safely and transparently.

The Long-Term Vision: Cybersecurity Without Incidents

Imagine an enterprise in 2045.

No emergency patch weekends.

No breach headlines.

No ransomware negotiations.

No frantic incident bridges.

Not because attacks stopped.

Because every meaningful attack has already been rehearsed millions of times inside autonomous simulations.

Every successful exploit has already been anticipated.

Every weakness has already evolved.

Every defense has already matured.

The organization no longer reacts to cyber threats.

It continuously outpaces them.

Conclusion: Security That Arrives Before the Threat

For decades, cybersecurity has resembled emergency medicine—rushing to treat injuries after they occur. The next era is better compared to preventive medicine, where continuous monitoring, simulation, and adaptation reduce the likelihood of harm before symptoms appear.

Preemptive Cybersecurity is not a single product, algorithm, or platform. It is a shift in philosophy: from defending against yesterday’s attacks to preparing for tomorrow’s possibilities.

Autonomous Defense Agents, digital twins, evolutionary attack simulation, counterfactual analysis, and self-improving security architectures together outline a future in which organizations no longer wait for attackers to reveal weaknesses. Instead, they discover and strengthen those weaknesses themselves, continuously.

The greatest transformation is conceptual.

Tomorrow’s strongest cyber defenses may not be the systems that detect attacks fastest.

They may be the systems that make the most dangerous attacks impossible long before anyone attempts them.

When security evolves from reaction to anticipation, the race between attackers and defenders changes fundamentally. The goal is no longer to win after the first move—it is to ensure the most damaging moves never become viable in the first place.

Falcon H1R

Falcon-H1R and the Dawn of the Cognitive Efficiency Era: How Hybrid Reasoning Architectures Are Democratizing Enterprise AI

For nearly a decade, the artificial intelligence industry has been trapped inside a singular belief: intelligence emerges primarily through scale. More parameters. More GPUs. More memory. More energy. More data centers.
Falcon-H1R represents a fundamental challenge to that doctrine.
Rather than asking how large a model can become, Falcon-H1R asks a more profound question:
How intelligent can a model become while consuming dramatically less?
The answer may redefine the future of enterprise AI.
By combining a hybrid architecture that unifies Transformer attention with State Space Memory systems and augmenting inference through DeepConf’s confidence-based reasoning methodology, Falcon-H1R demonstrates something that many believed impossible: elite reasoning performance delivered through radically improved computational efficiency.
This is not merely another model release.
It signals the beginning of what may become the most important shift in AI since the introduction of the Transformer itself:
The transition from General-Purpose Scaling to Cognitive Efficiency Engineering.
The implications extend far beyond model benchmarks.
They reach into robotics, autonomous systems, industrial automation, defense systems, healthcare devices, manufacturing equipment, IoT networks, edge computing, and ultimately every enterprise that has been priced out of advanced AI.
For the first time, sophisticated reasoning is becoming deployable where efficient models previously could not exist.


The End of the “Bigger Is Better” Era
The history of modern AI can be summarized through one equation:
More Parameters = More Capability
The industry rewarded organizations capable of building larger foundation models. Computational budgets exploded. GPU clusters expanded into planetary-scale infrastructure. Training runs began consuming millions of dollars worth of compute.
Yet enterprises encountered a growing paradox.
The most powerful models often became the least deployable.
Organizations discovered that possessing intelligence and operationalizing intelligence were entirely different challenges.
A manufacturing robot cannot rely on a distant cloud server for every decision.
An autonomous drone cannot wait for a data center response during flight.
A medical device cannot depend on unstable network connectivity.
An industrial inspection system cannot afford seconds of latency.
The AI industry solved intelligence.
It had not solved deployability.
This gap created a new frontier.
The future would not belong exclusively to the most intelligent systems.
It would belong to the most efficient intelligent systems.


Falcon-H1R’s Core Innovation: Hybrid Intelligence
The breakthrough behind Falcon-H1R lies in abandoning architectural purity.
Instead of relying solely on Transformer mechanisms, the system leverages a hybrid design integrating Transformer attention with State Space Models, creating complementary cognitive pathways. This hybrid approach was specifically engineered to improve reasoning efficiency, throughput, and long-context processing while reducing computational burden.
Traditional Transformers excel at:
• Pattern discovery
• Global context understanding
• Semantic relationships
• Complex reasoning
But they struggle with:
• Memory efficiency
• Long-context scaling
• Energy consumption
• Real-time deployment
State Space architectures contribute:
• Continuous memory retention
• Linear scaling characteristics
• Reduced computational overhead
• Superior efficiency over extended contexts
The hybrid architecture creates something entirely different:
Not a compromise.
A synthesis.
The Transformer becomes the strategic thinker.
The State Space system becomes the efficient memory engine.
Together they create a model capable of preserving reasoning quality while dramatically reducing operational cost.
This architectural philosophy mirrors biological intelligence.
Human cognition does not process every decision using full conscious reasoning.
Most cognitive activity relies on specialized subsystems optimized for efficiency.
Falcon-H1R introduces a similar principle into machine intelligence.


DeepConf: The Missing Layer in AI Reasoning
While hybrid architecture attracts attention, the deeper innovation may actually be DeepConf.
Traditional reasoning models often operate under a flawed assumption:
Every reasoning path deserves equal computational investment.
This creates enormous inefficiency.
Many reasoning chains reveal themselves as low-probability candidates early in the inference process.
Yet conventional systems continue spending resources exploring them.
DeepConf changes the economics of thought.
Instead of treating reasoning as a fixed process, it treats reasoning as a dynamically managed portfolio of cognitive investments.
The model continuously evaluates confidence signals.
High-confidence reasoning chains receive additional computational resources.
Low-confidence chains are terminated early.
Resources are reallocated toward more promising paths.
Research describing Falcon-H1R’s DeepConf evaluation reports substantial reductions in token consumption while maintaining or improving reasoning performance through confidence-guided pruning and aggregation.
This is an extraordinarily important shift.
Historically, AI optimization focused on reducing computation before inference.
DeepConf optimizes intelligence during inference.
The model becomes self-aware of reasoning quality in real time.
In effect, the system learns not only how to think.
It learns when thinking further is unnecessary.


The Birth of Cognitive Resource Management
DeepConf introduces what may become an entirely new discipline:
Cognitive Resource Management (CRM)
Just as operating systems manage CPU cycles and memory allocation, future AI systems will manage reasoning allocation.
Questions will no longer be:
• Can the model answer?
• How large is the model?
Instead:
• How much reasoning is required?
• Which reasoning path deserves investment?
• When should computation stop?
This transforms AI from static computation into adaptive cognition.
The economic implications are enormous.
Every unnecessary token becomes a measurable business cost.
Every avoided inference cycle becomes profit.
Every watt saved becomes scalability.


Why Robotics Changes First
The greatest beneficiary of this shift may not be software.
It may be robotics.
Robots operate under harsh constraints:
• Limited memory
• Limited battery capacity
• Limited thermal budgets
• Real-time requirements
• Continuous operation
Traditional large-scale reasoning models are fundamentally incompatible with these realities.
Falcon-H1R changes the equation.
A robot equipped with efficient hybrid reasoning gains access to capabilities previously reserved for cloud infrastructure:
• Dynamic planning
• Contextual reasoning
• Environmental understanding
• Adaptive decision-making
• Multi-step problem solving
Without requiring a hyperscale data center.
This creates the possibility of truly autonomous edge intelligence.
Not cloud-assisted intelligence.
Not periodically synchronized intelligence.
Native intelligence.
The distinction is transformative.


The Edge Computing Revolution Nobody Predicted
For years, edge AI was viewed as a reduced version of “real AI.”
Smaller models.
Lower accuracy.
Limited functionality.
Compromised reasoning.
Falcon-H1R suggests a different future.
Edge AI may become the dominant deployment paradigm.
Why?
Because enterprises do not purchase benchmarks.
They purchase outcomes.
A slightly smaller model deployed across 100,000 devices often creates more business value than a giant model confined to centralized infrastructure.
This inversion changes investment priorities.
Success becomes measured not by model size but by deployment density.
The winners become organizations capable of placing intelligence everywhere.


Enterprise AI’s Next Phase: Specialization Over Generalization
Perhaps the most significant implication is what Falcon-H1R reveals about the future of enterprise AI.
The industry is moving from:
“One model for everything”
toward
“The right model for each task.”
This shift resembles the evolution of software itself.
Early computing relied on monolithic systems.
Modern computing relies on specialized services.
AI is entering the same transition.
Future enterprises will deploy ecosystems of models:
• Financial reasoning models
• Supply-chain optimization models
• Manufacturing intelligence models
• Healthcare reasoning models
• Legal analysis models
• Customer service models
Each optimized for specific objectives.
Each delivering maximum efficiency.
Each operating at dramatically lower cost.
The age of universal intelligence is giving way to the age of contextual intelligence.


Democratizing Enterprise AI
Historically, advanced AI favored large organizations.
The barriers were immense:
• GPU access
• Infrastructure budgets
• Specialized talent
• Massive operating costs
Falcon-H1R challenges those assumptions.
When reasoning becomes more efficient, intelligence becomes more accessible.
A startup can deploy capabilities previously available only to Fortune 500 companies.
A regional manufacturer can build intelligent automation systems.
A hospital can operate advanced diagnostic assistants locally.
A logistics provider can run optimization models on-site.
Efficiency becomes a democratizing force.
The next wave of AI adoption may not be driven by technology giants.
It may be driven by organizations that were previously excluded from the AI economy.


The Emergence of AI Economics 2.0
The first generation of AI economics focused on capability.
The second generation will focus on efficiency.
Three metrics will increasingly determine competitive advantage:
Intelligence per Watt
How much reasoning can be delivered per unit of energy?
Intelligence per Dollar
How much business value can be generated per unit cost?
Intelligence per Megabyte
How much capability can be delivered within constrained hardware environments?
Falcon-H1R is one of the earliest models explicitly optimized across all three dimensions.
This is why its significance extends beyond benchmark performance.
It represents a new optimization target.


The Future: Intelligence Everywhere
The long-term consequence of Falcon-H1R’s design philosophy is straightforward.
AI will stop being a destination.
It will become infrastructure.
Invisible.
Embedded.
Ubiquitous.
Every machine.
Every device.
Every workflow.
Every enterprise process.
Not because models become larger.
But because they become efficient enough to disappear into the environment.
This is the true promise of hybrid architectures and confidence-driven reasoning.
Not merely faster AI.
Not merely cheaper AI.
But deployable intelligence at planetary scale.


Conclusion
Falcon-H1R signals a profound transition in artificial intelligence.
Its hybrid architecture demonstrates that reasoning performance no longer requires exponential growth in model size. Its DeepConf framework shows that intelligence can be dynamically optimized during inference rather than simply scaled through brute-force computation. Together, they establish a new paradigm where memory efficiency, energy efficiency, reasoning quality, and deployment flexibility become equally important objectives.
The broader significance extends beyond a single model.
It points toward a future dominated by specialized, efficient, task-focused AI systems operating across robotics, edge computing, industrial automation, and enterprise infrastructure.
The next chapter of AI will not be written by the largest models.
It will be written by the most deployable ones.
And in that future, Falcon-H1R may be remembered as one of the earliest signals that the age of scaling was giving way to the age of cognitive efficiency.

Micro fluidics

Microfluidic On-Chip Cooling: Solving the AI Thermal Crisis

Introduction: The AI Industry’s Invisible Emergency

The world is focused on bigger AI models, larger data centers, and increasingly powerful accelerators. Yet behind every breakthrough lies a rapidly escalating problem that few outside semiconductor engineering fully appreciate:

Heat is becoming the fundamental bottleneck of artificial intelligence.

For decades, computing performance was constrained primarily by transistor density, clock frequency, memory bandwidth, and power delivery. Today, a new limiting factor has emerged—thermal physics itself.

The irony is striking. Humanity has learned how to place hundreds of billions of transistors onto a piece of silicon smaller than a postcard. We can train trillion-parameter models and perform quadrillions of operations per second.

Yet we still struggle to remove the heat generated by those calculations.

Modern AI accelerators are approaching thermal densities comparable to nuclear reactor cores in localized regions. Some next-generation AI chips are projected to exceed 2,000 watts of power consumption per package. Traditional cooling methods—airflow, copper heat spreaders, heat pipes, and even liquid cold plates—are beginning to encounter the hard limits of physics.

The future AI crisis may not be computational.

It may be thermal.

And the solution could involve something that sounds almost impossible:

Building microscopic rivers directly inside the silicon itself.

This is the emerging frontier of Microfluidic On-Chip Cooling.

Not cooling around the chip.

Not cooling above the chip.

Cooling through the chip.

The End of Traditional Cooling

To understand why microfluidics matters, we must first understand why existing approaches are approaching failure.

Today’s AI chips generate heat through billions of switching transistors.

Every operation creates energy loss.

Every matrix multiplication creates thermal buildup.

Every inference contributes microscopic temperature increases.

At small scales, this isn’t problematic.

At AI scale, it becomes catastrophic.

Traditional cooling follows a relatively inefficient thermal journey:

Transistor → Silicon → Heat Spreader → Thermal Interface Material → Cold Plate → Coolant

Every step introduces resistance.

Every layer slows heat removal.

Every micron matters.

By the time heat reaches external cooling systems, valuable milliseconds have passed and temperatures have already risen.

This creates thermal hotspots.

Hotspots reduce efficiency.

Reduced efficiency requires more power.

More power generates more heat.

The cycle becomes self-reinforcing.

Engineers call this the Thermal Wall.

Many believe AI is now colliding with it.

The Revolutionary Idea: Cooling From Within

Imagine a city suffering from extreme summer temperatures.

One solution is to place giant fans around the city.

Another is to create underground water channels beneath every street.

Which removes heat faster?

The second.

Microfluidic cooling applies this exact principle to silicon.

Instead of removing heat after it reaches the surface, engineers etch microscopic channels directly into semiconductor substrates.

These channels are often thinner than a human hair.

Coolant continuously flows through them.

Heat is extracted at the point of generation.

Not centimeters away.

Not millimeters away.

Sometimes only microns away.

The result is transformative.

Heat no longer needs to travel long distances.

Thermal resistance collapses.

Cooling efficiency skyrockets.

Research simulations suggest that advanced embedded microfluidic systems could remove heat several times faster than conventional package-level cooling approaches.

The implications extend far beyond temperature reduction.

They fundamentally alter chip architecture itself.

Silicon Becomes a Living Circulatory System

One way to understand this technology is through biology.

The human body solved thermal management hundreds of millions of years ago.

Blood vessels transport heat away from active muscles.

Capillaries distribute cooling exactly where it is needed.

Fluid continuously adapts to changing workloads.

Microfluidic AI chips mimic this principle.

Instead of static cooling systems, processors become dynamic thermal organisms.

Thousands of microscopic channels form a circulatory network.

Coolant enters.

Heat is absorbed.

Temperature gradients flatten.

Thermal equilibrium is maintained.

Future chips may contain billions of transistors and thousands of fluid pathways working simultaneously.

The processor no longer resembles a machine.

It resembles an engineered ecosystem.

Beyond Water: The Rise of Intelligent Coolants

One of the least explored opportunities in microfluidics is the coolant itself.

Most discussions assume water-like fluids.

Future systems may be dramatically more sophisticated.

Imagine coolants engineered at the molecular level.

Fluids that alter thermal conductivity based on workload.

Nanoparticle-enhanced liquids capable of transporting heat more efficiently than conventional coolants.

Phase-changing fluids that evaporate and condense inside microscopic chambers.

Magnetically steerable cooling streams.

Self-healing thermal liquids capable of detecting contamination and repairing circulation paths.

Researchers are beginning to explore fluids that behave less like water and more like programmable thermal materials.

In such systems, cooling becomes computational.

The coolant becomes an active participant in performance optimization.

Thermal Computing: A New Design Philosophy

Historically, chip architects treated cooling as a secondary consideration.

Design the processor first.

Cool it afterward.

Microfluidics reverses that philosophy.

Thermal management becomes a foundational design parameter.

Future processors may be designed around heat flow patterns before transistor layouts are finalized.

This gives rise to a concept we might call:

Thermal Computing Architecture.

Instead of asking:

“Where should we place the transistors?”

Engineers ask:

“Where should heat travel?”

This subtle shift could redefine semiconductor design.

Computational units may migrate based on cooling accessibility.

AI cores may cluster around fluid-rich regions.

Memory systems may be distributed according to thermal pathways.

Cooling infrastructure becomes part of the computational architecture itself.

The Era of Three-Dimensional AI

The semiconductor industry increasingly relies on 3D stacking.

Processors are no longer spreading outward.

They are growing upward.

Logic layers.

Memory layers.

Photonic layers.

Interconnect layers.

Everything stacked vertically.

The challenge?

Heat becomes trapped.

Like apartments in a skyscraper with no ventilation.

Microfluidics changes the equation.

Embedded channels can snake through stacked layers.

Heat extraction occurs between computational tiers.

This enables true vertical computing.

Without advanced cooling, many future 3D architectures would remain impractical.

With microfluidics, they become viable.

The next generation of AI systems may look less like flat chips and more like computational skyscrapers filled with microscopic cooling rivers.

Why AI Specifically Needs This Technology

AI workloads are uniquely demanding.

Traditional software creates bursts of activity.

AI creates sustained thermal pressure.

Training large language models involves weeks or months of continuous computation.

Temperatures remain elevated for extended periods.

This introduces multiple challenges:

  • Thermal throttling
  • Efficiency degradation
  • Material fatigue
  • Electromigration
  • Reduced lifespan
  • Power waste

Microfluidic cooling directly addresses each of these issues.

Lower temperatures improve transistor behavior.

Signal integrity improves.

Leakage currents decrease.

Reliability increases.

Performance becomes more predictable.

In some projections, thermal optimization could deliver efficiency gains comparable to entire process-node advancements.

That means cooling could become as important as transistor scaling.

The Emergence of Self-Aware Thermal Systems

Perhaps the most fascinating future development is the convergence of AI and cooling.

Imagine chips with embedded thermal intelligence.

Thousands of sensors monitor heat generation in real time.

Machine learning algorithms predict hotspot formation before it occurs.

Fluid flow is dynamically redirected.

Pressure changes automatically.

Cooling capacity migrates throughout the processor.

The chip effectively regulates its own temperature.

Like a biological organism sweating before overheating.

This concept—Autonomous Thermal Management—may become a defining feature of future AI infrastructure.

The cooling system itself becomes AI-powered.

The Data Center Transformation

The impact extends far beyond individual chips.

Modern AI data centers consume enormous amounts of electricity.

A significant portion supports cooling infrastructure.

As processors become hotter, cooling expenses rise dramatically.

Microfluidic architectures may fundamentally reshape facility design.

Future data centers may:

  • Require fewer mechanical cooling systems
  • Reduce airflow infrastructure
  • Increase rack density
  • Lower energy consumption
  • Shrink physical footprints
  • Improve sustainability metrics

The economics are profound.

Every watt saved in cooling can unlock additional computational capacity.

At hyperscale, this translates into billions of dollars.

The Manufacturing Challenge Nobody Talks About

The promise is enormous.

The engineering challenge is equally massive.

Embedding fluid channels inside silicon introduces unprecedented manufacturing complexity.

Engineers must solve:

  • Channel reliability
  • Fluid leakage prevention
  • Corrosion resistance
  • Pressure regulation
  • Long-term durability
  • Packaging integration
  • Maintenance strategies

A single microscopic defect could impact cooling performance.

Yield management becomes extraordinarily challenging.

Yet semiconductor history suggests a recurring pattern:

Every seemingly impossible manufacturing challenge eventually becomes routine once economic incentives become large enough.

AI has created those incentives.

The Future: Chips That Think Like Ecosystems

The most important insight may be this:

Microfluidic cooling is not merely a thermal technology.

It represents a philosophical shift.

For decades, computing systems were designed as static structures.

Future systems may behave more like living environments.

Fluid circulation.

Adaptive regulation.

Dynamic resource allocation.

Self-optimization.

Thermal awareness.

Biological inspiration is becoming increasingly visible in engineering.

Microfluidic AI chips are among the clearest examples.

The processor evolves from a passive object into an active thermodynamic system.

Conclusion: The Hidden Innovation That Could Sustain the AI Revolution

History often remembers visible breakthroughs.

The transistor.

The microprocessor.

The GPU.

The neural network.

Yet many technological revolutions are enabled by less glamorous innovations operating behind the scenes.

Microfluidic on-chip cooling may become one of those innovations.

As AI models continue expanding, computational demand will eventually exceed what traditional cooling methods can support.

At that moment, performance improvements will depend not on smarter algorithms or smaller transistors, but on our ability to move heat.

The future of artificial intelligence may ultimately be determined by something surprisingly simple:

How effectively we can circulate tiny streams of liquid through microscopic channels inside silicon.

In that future, the most advanced AI processor on Earth may not be distinguished by the number of transistors it contains.

It may be distinguished by the sophistication of the invisible rivers flowing through its core.

And those rivers could become the foundation upon which the next century of computing is built.